josalhor
Re:The Navier–Stokes Millennium Prize Problem
on Wednesday September 09, 2026 @03:11AM (#49622452)
1. I know, but that is somewhat irrelevant to my question
2. I am indeed a CS PhD student (well, I am finishing now)
> If OAI is using chat data from researchers to make discoveries, essentially every researcher who chats with an LLM can get scooped
But they make very clear that they do train on this if you do not disable the setting. We can comment on the fact that this is opt out instead of opt in, but this discourse of OAI sniping the solution out of some researchers hands seems to be running on the best case speculation of the researchers having perfectly handled all their chats and discussions with other researchers and the worse case of OAI not having full pipeline control and I think that is an unfair assumption.
Re:The Navier–Stokes Millennium Prize Problem
on Wednesday September 09, 2026 @03:07AM (#49622403)
Have the other researchers opted out? On all their accounts? Through the entire time? And did they discuss this with anyone else? And did those people ask ChatGPT stuff? And did they disable it? If I was OpenAI, I would be very careful about my wording here when making claims of "we have never trained on any of their ideas directly or indirectly".
Re:The Navier–Stokes Millennium Prize Problem
on Wednesday September 09, 2026 @02:54AM (#49622259)
But why is this news? This is clearly described in their ToS and in the Settings to improve their models.
Re:The Navier–Stokes Millennium Prize Problem
on Wednesday September 09, 2026 @02:40AM (#49622135)
I think this drama was blown up a bit out of proportion. The entire discourse I am seeing online seems to revolve around this:
> While unlikely, we cannot rule out that de-identified data derived from their usage of our products helped improve our models
I mean... yeah? What do you expect? What else can they say? How could you prove a negative in this case? I do not want to comment on specific OAI employee chat messages, but on the actual OAI discovery here.
Re:Stop Killing the Internet: No Digital ID and No Age Verification
on Tuesday July 28, 2026 @05:05PM (#49089894)
I want the right to not be identified.
I also want the right to SELF identify.
I think the toxic culture of the internet has happened in part because anonymity leads to lack of accountability. I want to self identify and interact with other people who also self identify. The cost of running LLM botnets is going down. I cannot imagine how the next cycle of elections is going to be like on all countries. I understand the right to remain anonymous, that should remain, but that state should not be the default on these massively big platforms. Our brains and political systems are not designed for this.
And no, "get people to get rid of their smartphone voluntarily" like I see on the comments is not going to happen.
Re:Wayfinder Router: deterministic routing of queries between local an...
on Sunday June 28, 2026 @10:54AM (#48707855)
> Well… it doesn’t exist FROM APPLE or MICROSOFT or GOOGLE at their shipped OS
What I am saying does not exist period. What I am saying is that there isn't a proper abstraction that helps the ecosystem build upon it.
> But I think the parents post is suggesting YOU CAN BUILD a prototype of what you want, how it should work, on Linux
I mean, yes. But me saying "this does not exist" and someone saying "but you can build it" does not take away from the fact that... Yeah, it doesn't exit :).
And also, no, I cannot build it, at least not alone. Because I want apps to eventually build upon my abstractions. This would require a good set of millions, of which the technical development would be a small part. The coordination, contracts, API definitions, even marketing, etc would be the majority.
I am saying something that Google, Telefonica, Microsoft etc could do.
Re:Wayfinder Router: deterministic routing of queries between local an...
on Sunday June 28, 2026 @10:49AM (#48707809)
> Chat completions is just a network call like anything else
But what if Chat completion was resolved locally with hardware? Or what if I want my OS to coordinate Chat completions locally and, if my hardware is overwhelmed, send some to network?
You do have a valid point, yes, that what I am saying, without support for local hardware could be done with a sort of Open Router equivalent.
> they don’t need to pay separately (they can use the same account), they just pass their API key over the network to the completions server
That I would be conformable putting what I am saying on my parents phone. I do no trust my parents to manage API keys. What I am saying is an ecosystem thing, not only a low level thing
Re:Wayfinder Router: deterministic routing of queries between local an...
on Sunday June 28, 2026 @10:46AM (#48707779)
Querying a CLI is also querying an API. I never said API endpoint. An API can be a Java Interface, a CLI, an endpoint etc.
Re:Wayfinder Router: deterministic routing of queries between local an...
on Sunday June 28, 2026 @08:30AM (#48706728)
No, what I am saying simply does not exist yet.
I am saying I want my OS to expose APIs like it does for the disk or the network for AI. And I want my apps to be able to use those APIs.
I want my backend LLMs to be able to change on a whim. Imagine an Android app consuming from these LLMs. Maybe I am outside and it is making queries to Gemini. And maybe I get home and now it makes queries to my local llm, almost like connecting to local Wifi.
What I am saying does not exist on many levels:
- Agreed upon APIs for this don't think exist (in text maybe, but not in image/sound/video).
- OSs do not expose this (I am not talking manually configured user space stuff here).
- I see a world where your Network provider bundles "calls + data plan + AI tokens". But not only are the offerings for these not standardized, in order to even reach that point we would need to standardize the offerings. How do you compare intelligence among models? How do you compare cost?
- The apps need to start adopting this model
The tech is here, the ecosystem is not.
Re:Wayfinder Router: deterministic routing of queries between local an...
on Sunday June 28, 2026 @04:17AM (#48705423)
We need LLM query routing at the OS level like Mobile data.
I know it will sound crazy but hear me out. I think about this AI inference as infrastructure. I do not want to pay for it on every app I use it on. I do not think "I have to pay the mobile data of youtube, and the mobile data of whatsapp etc.". I pay Mobile data infrastructure and let my device route it appropiately. In fact, if we ever go the local llm route, you could have LLM capabilities without having access to the internet (or local LAN), and your OS/computer is the only one capable of doing that routing for you.
Re:Security Through Obscurity Is Not Bad
on Sunday May 03, 2026 @12:19PM (#47998491)
I want to add that Obscurity is ambiguous.
Is changing the port of SSH "obscurity"?
Some may say yes, because you could find it by bruteforce.
But a password with infinite attempts can also be bruteforced.
Here, the defining factor of security is maximum number of attempts (either on ports, username or whatever).
Re:RAM Has a Design Flaw from 1966. I Bypassed It [video]
on Friday April 10, 2026 @02:50AM (#47714448)
I haven't had time to see the whole thing yet, but I'm quite surprised this yielded good results. If this works I would have expected CPU implementations to do some optimization around this by default given the memory latency bottleneck of the last 1.5 decades. What am I missing here?
Re:I put all 8,642 Spanish laws in Git – every reform is a commit
on Saturday March 28, 2026 @09:41AM (#47554516)
Not only would be cool for laws to have appropiate time stamps so we can "go back in time to how it was at a certain moment", but also if we could have proper git commit diffs of how laws change over time. See this: https://www.boe.es/buscar/act.php?id=BOE-A-2015-11430
You can see how certain articles have the option to check "how that particular article was at each moment in time". That would be way harder to track, but it would be awesome if not only could you "go back in time and see what the law was" but also "how its been evolving".
Re:Samsung Galaxy S26 Ultra Review: The Privacy Screen
on Wednesday March 18, 2026 @05:38PM (#47431749)
People use their phone today to: Manage 100k+,1M+ bank accounts, 2FA, secret messaging, sensitive media, medication, credentials and more.
This privacy feature makes a lot of sense.
Give it a couple of iterations and I think this will be the standard in business. It never made sense to me the trust that we put on no one looking at the contents of a display at the same time as us.
Re:Python: The Optimization Ladder
on Saturday March 14, 2026 @09:33AM (#47376514)
While this is great, I expected faster CPython to eventually culminate into what YJIT for Ruby is. I'm not sure the current approaches they are trying will get the ecosystem there.
Re:Is legal the same as legitimate: AI reimplementation and the erosio...
on Monday March 09, 2026 @06:23PM (#47316513)
I think the direction we are going, the GPL is going to fade away. I think people will look at this like writing a book and claiming the ideas in the book cannot be copied. This debate is not that different from the ones going on in the music industry. I open sourced my latest software as Apache 2.0 after debating a lot about this. Unless the FSF wins in court in the next <=2-3 years, there is no coming back from this.
Re:GPT‑5.3 Instant
on Tuesday March 03, 2026 @03:01PM (#47238086)
Reminder that OpenAI serves a lot of customers for free, most of the people I know use the free tier. There is a big limit on thinking queries on free tier, so a decent non thinking model is probably a positive ROI for them.
Re:What is f(x) ≤ g(x) + O(1)? Inequalities With Asymptotics
on Monday February 23, 2026 @06:38PM (#47130671)
> computer science students should be familiar with the standard f(x)=O(g(x)) notation
I have always thought that expressing it like that instead of f(x) ∈ O(g(x)) is very confusing. I understand the desire to apply arithmetic notation of summation to represent the factors, but "concluding" this notation with equality, when it's not an equality... Is grounds for confusion.
Re:Gemini 3.1 Pro
on Thursday February 19, 2026 @12:49PM (#47076687)
Sorry... I speculated that 3 deep think is 3.1 pro.. model names are confusing..
Re:Gemini 3.1 Pro
on Thursday February 19, 2026 @11:39AM (#47075681)
I speculated that 3 pro was 3.1... I guess I was wrong. Super impressive numbers here. Good job Google.
Re:Gemini 3 Deep Think
on Thursday February 12, 2026 @01:39PM (#46993081)
I think this is 3.1 (3.0 Pro with the RL improv of 3.0 Flash).
But they probably decided to market it as Deep Think because why not charge more for it.
Re:Vitamin D and Omega-3 have a larger effect on depression than antid...
on Thursday January 29, 2026 @06:19AM (#46808666)
I also noticed that.
Opened issue: https://github.com/ncase/blog/issues/4
Re:Television is 100 years old today
on Monday January 26, 2026 @02:32PM (#46770381)
On the one hand I look at some tech lifecycles and feel everything moves so slow (cars, energy and train infrastructure etc..). And then I look at other stuff and I cannot phantom that someone who was born 100 years ago saw a TV (or media electronic screen) from conception to modern miracle. As someone in his 20s I can't imagine what I'll see in the next 80 years!
Re:Speculation of Donut Lab Solid State Battery [video]
on Friday January 16, 2026 @08:57AM (#46646374)
I found this video on battery chemistry very interesting. Even if Donut claims about the batteries are not true, I still feel I learned quite a bit about batteries from this video. Of course, if they figured this out, a nobel of chemistry is probably in line.
Re:Ask HN: Could you share your personal website here?
on Wednesday January 14, 2026 @02:26PM (#46621396)
https://josalhor.com/
Mainly CV; a tad outdated (no 2025 info)
Re:The No Fakes Act Has a "Fingerprinting" Trap That Kills Open Source
on Friday January 09, 2026 @02:32AM (#46551017)
We do have tech that is "behind doors". Just look at military applications (nuclear, tank and jet design etc). Should "clonable voice and video" be behind close doors? Or should AGI be behind close doors? I think that the approach of the suggested legistation may not the right way to go about; but at a certain level of implementation capability I'm not sure how I would handle this situation.
If current tech appeared all of a sudden in 1999; I am sure as a society we would all accept this, but slow boiling frog theory I guess.
Re:It's hard to justify Tahoe icons
on Monday January 05, 2026 @07:00PM (#46506985)
> of the reasons I use Apple systems was they had the UI stuff nailed down (...) Lately it's just a mess
I have never daily driven an Apple device, so I can't comment on this; but from what I seen I do agree that Apple UI has not been as consistent lately.
> ps I assume by the opening image, you mean the first screenshot supplied by the author of the article
Yeah, sorry about that; that's correct, that's what I'm referring to. To remove ambiguity: https://tonsky.me/blog/tahoe-icons/sequoia_tahoe_textedit@2x...
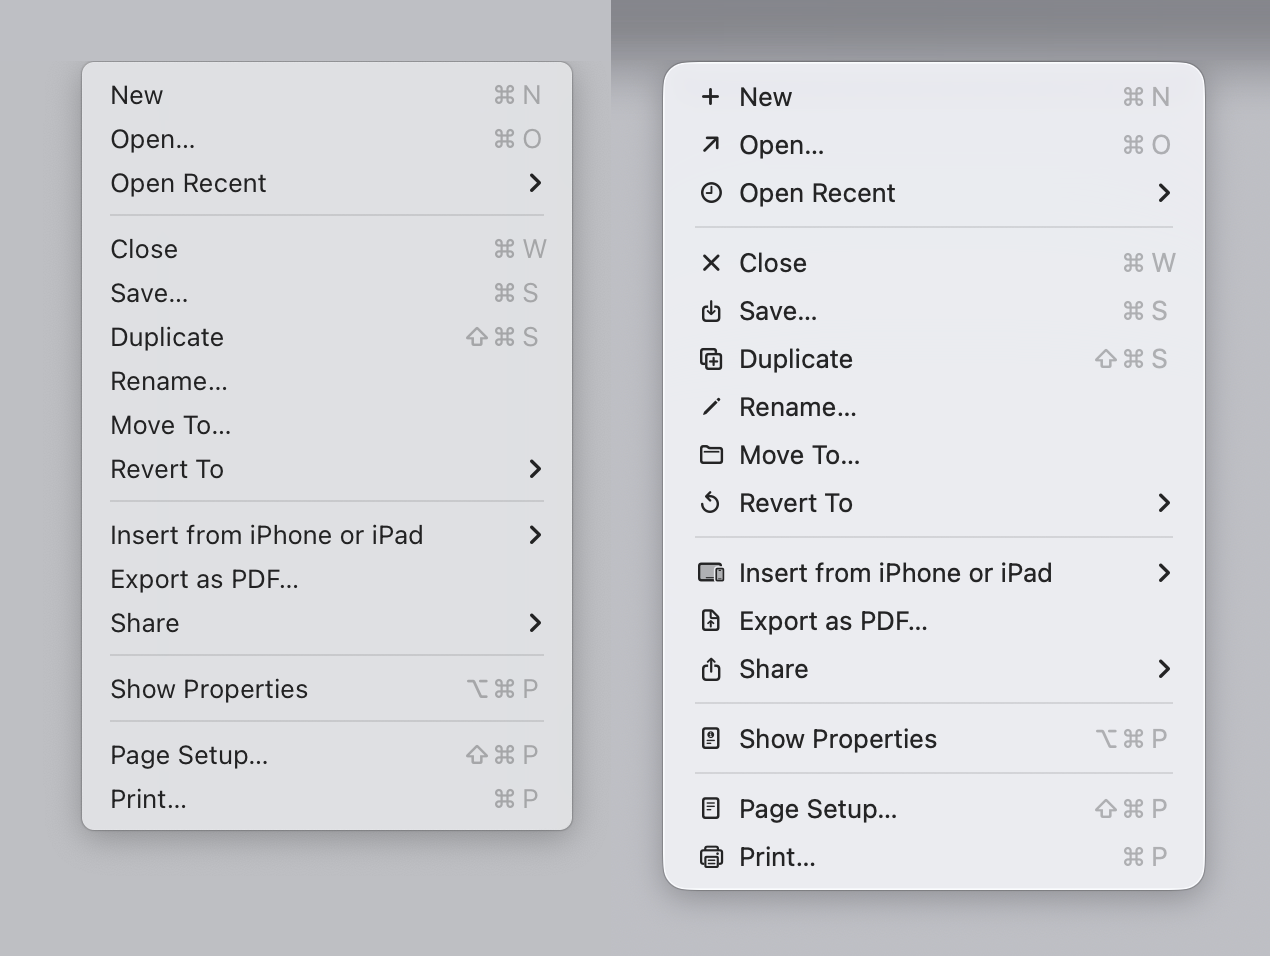
> How does a list of icons that are used inconsistently, duplicated, used in other places, sometimes used and sometimes not used, not to mention illegible, positioned inconsistently, go directly against the broad (reasoned) rules of the Apple HIG, help 'make it easier' as you say?
Sure! First of all, I'm only commenting on the FIRST image of the blog. There are no duplicated images in it. The icons appear consistently used in that image (maybe export to PDF looks a bit off, but this is a pattern that I have seen repeated on other apps, so I'm used to it). I'm not sure how the icons would look on the actual display, but they look alright on my 4K display as shown on the blog. I also can't comment on they being used "inconsistently" across other parts because I don't use Apple devices.
I'm making a very narrow claim: On the first image, if I compare the menu on the left, with the menu on the right, I prefer the menu on the right. I have tried to "find X" on a menu on the left and then repeat a similar exercise on the right; I am faster on the right and I am more confident on the right. My brain seems to be using the icons as a "fast lookup" and the text to verify the action.
Now, does this translate to all other menus? No! The "File" example he shows is super confusing. Also, it's possible I would prefer the less cluttered version with less icons. But for me (all icons) > (no icons) on that specific example.
I have not put enough mental energy to agree with the author on all of his individual suggestions across the article, but they look overall fine on the individual examples he provides. I'm just find the first example... not particularly compelling.
> Well - that's just your --- opinion, man
Well... Yes. But unless we objectively measure how I use the computer, that's the best we have got to evaluate my preference.
All my classes on human-computer interaction and design has always been about "listen to your users".
Re:It's hard to justify Tahoe icons
on Monday January 05, 2026 @02:38PM (#46503647)
> most of your points are refuted in the article
Sure, we can debate about the general points.
Yet, we can't refute that my subjective opinion evaluation of the opening image looks better (for me) , reads better (for me) and is easier (for me) to parse. Either I don't fit the general guidelines, or the general guidelines need a revision, that's my point overall.
Re:It's hard to justify Tahoe icons
on Monday January 05, 2026 @07:37AM (#46498088)
Interesting.
The article starts with this: > Sequoia → Tahoe It’s bad
And I look at the image... And I like it? I agree with the author that it could be better, but most of the icons (new, open recent, close, save, duplicate, print, share etc), do make it easier, faster and more pleasant for my brain to parse the menu vs no icons.
Again, I don't disagree that you could do it better, I just disagree with the premise that the 1992 manual is "the authority". Display density has increased dramatically; people use their computers more and have been accustomed to those interfaces, which makes the relationship of the people with the interfaces different. Quoting a 1992 guideline on interfaces in 2026 feels like quoting the greeks on philosophy while ignoring our understandings of the world since then.