jliszka
Re:Search at Slack
on Thursday February 09, 2017 @02:37PM (#13610122)
Stay tuned! We're working on improving phrase matching as we speak.
As for the Control-F thing... stay tuned on that too :)
Re:Search at Slack
on Thursday February 09, 2017 @08:47AM (#13606832)
Stay tuned :)
Re:Search at Slack
on Wednesday February 08, 2017 @03:13PM (#13601594)
Yep. We normalize our features as part of training, and the stdevs of each feature are part of the resulting model, along with the weights. (The means are always 0 because of the way we construct our training set.) The weights we use in production are actually normalized_weight / stdev.
Probability is in the process
A Toy Kafka Reimplementation in Go with GRPC
Programming with Futures: patterns and anti-patterns
Re:Bayesian networks and causality
on Wednesday December 18, 2013 @01:44PM (#6929594)
yes
Bayesian networks and causality
The Foursquare Theorem
Re:Painless, effective peer reviews
on Friday November 08, 2013 @11:28AM (#6697103)
That would be ideal, but a lot of people are uncomfortable doing that, and you would not get critical feedback as often or as reliably.
Painless, effective peer reviews
Infinite lazy polynomials
Re:Exact numeric nth derivatives
on Thursday October 24, 2013 @02:59PM (#6607177)
You're right, it is begging the question, for any simple function, you basically have to tell it what all the derivatives are for it to work.
The power of this technique is that it handles the product rule and chain rule for you, so composition and multiplication of functions work automatically without extra work.
For the case of 1/(1-x), you only need to tell it the derivatives (wrt x) of
f(x, a) = x * a
g(x, a) = x + a
h(x) = 1/x
Then it automatically knows how to compute the derivatives of h(g(f(x, -1), 1)).
Re:Exact numeric nth derivatives
on Thursday October 24, 2013 @02:33PM (#6607008)
Thanks! fixing...
Re:Exact numeric nth derivatives
on Thursday October 24, 2013 @02:28PM (#6606977)
You're right, there's only O(n) information in these particular n x n matrices, so you can multiply them in O(n^2).
The code provided memoizes cell values using the key (r - c), so only O(n^2) work is required to read off the top row of the matrix. I'm planning to make that more explicit in a follow-up post.
Exact numeric nth derivatives
Some impossible functions
Understanding A/B test analysis
Re:How traffic actually works
on Tuesday October 01, 2013 @08:39PM (#6479952)
Thanks! What's your research on?
Re:How traffic actually works
on Tuesday October 01, 2013 @04:04PM (#6478729)
Yeah, I failed there. The whole article started out jokey but I ended up cramming a bunch more "serious" analysis in.
Re:How traffic actually works
on Tuesday October 01, 2013 @03:58PM (#6478694)
Really appreciate the feedback, comes with the territory :)
I added an update to the article looking at what happens when you vary the average car length (corresponding to the % of trucks on the road), fwiw.
Re:How traffic actually works
on Tuesday October 01, 2013 @03:55PM (#6478677)
FWIW I tried this out, seeing what happens when there are varying average car lengths on the road.
http://jliszka.github.io/assets/img/traffic/speed-vs-occupan... http://localhost:4000/assets/img/traffic/flow-vs-occupancy-2...
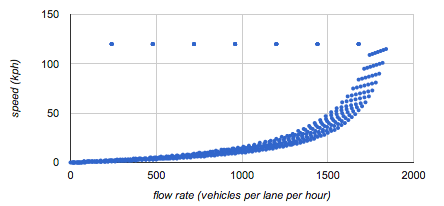

Also added as an update to the article.
Re:How traffic actually works
on Tuesday October 01, 2013 @03:12PM (#6478412)
> You can see on the right side how his "cars per second" is _exactly the same_ than on the left side.
Yes, but there are way more cars on the left side. That is the difference. Occupancy (density) determines speed when flow rate is fixed, and that graphic is actually a perfect illustration of this. You can't make the cars on the left travel at 80mph because it would not allow for a safe following distance.
One thing that is the same on both sides is that if you're the nth car back from the merge, it's going to take 2n seconds for you to get to the merge. Yes, the important thing is how many miles you can cover in that time, but this way of thinking places an upper limit on how many miles that can be, based on the occupancy of the road.
Also, pretty sure the advice at the end was tongue-in-cheek ;)
Re:How traffic actually works
on Tuesday October 01, 2013 @01:49PM (#6477789)
OP here. That's a really good point. I just think the original article overreached in saying that zipper merging is a "simple cure" for traffic jams, without taking into account that the road might at or near capacity (and you hit capacity in a hurry when you lose a lane).
My article doesn't account for variance in flow rates in congested traffic, but variance in car length (% of trucks on the road) might explain it. I'm not convinced that merging behavior is the culprit; the original article only speculates that that's the case. I'm putting forward a reasonable explanation for why that isn't the explanation, and a basis for evaluating whether it might be — in particular, whether a zipper merge results in higher flow rates after the bottleneck.
Re:How traffic actually works
on Tuesday October 01, 2013 @12:48PM (#6477325)
OP here, excellent point. Since so much is determined by occupancy (cars per km), I think the only way to switch domains is to lower the road's occupancy, which is exactly what you're doing when you leave extra space in front of you. However, I tried to point out that this probably comes at the expense of increased occupancy somewhere else, so you're just moving the jam around.
Re:How traffic actually works
on Tuesday October 01, 2013 @12:06PM (#6477027)
That was a joke ;) Onramp regulators are the real answer, letting only 1 car merge into traffic at a time at a rate well under 1 every 2 seconds.