bzillins
Re:Flighty Airports
on Wednesday March 25, 2026 @10:09AM (#47517566)
Flighty was recommended to me by a flight attendant and I also have been notified hours ahead of the airlines by it.
Re:Why Using Cassandra as a metadata database for an object store is a...
on Monday January 18, 2021 @03:19PM (#25826116)
NetApp StorageGRID uses Cassandra according to their docs. "Three copies of object metadata are automatically maintained at each site to provide redundancy and protect object metadata from loss. The copies are load balanced across all Storage Nodes at each site."
Re:To All the Jobs I Had Before
on Friday September 18, 2020 @07:44PM (#24522982)
This was required reading for an engineering management course and is one of the few texts that I find myself thinking back on many years later. I strongly second this recommendation.
Re:The Dream of New York's Forgotten Elevated Subway
on Tuesday October 15, 2019 @08:25PM (#21265693)
The NYC blizzard of 1888 had a large impact on the city's decision to build subways which started construction in 1900.
https://www.nycsubway.org/wiki/The_Blizzard_of_1888;_the_Imp...
Databricks Open Sources Delta Lake
Re:Ice cold archive storage
on Thursday April 11, 2019 @11:02AM (#19635160)
The title seems like a reference to the 2003 Outkast song Hey Ya!
https://www.youtube.com/watch?v=PWgvGjAhvIw
Alright alright alright!
Optimizing for Workloads: Linux Spinlocks vs. Mutexes
Best way to count distinct indexed things in PostgreSQL
How to evaluate your next database
Re:Tips for your first tech conference
on Tuesday March 19, 2019 @09:01PM (#19437856)
I completely agree that breakfast at conferences has been a fantastic opportunity to meet fellow attendees. Conversation is quite easy to strike up by asking which talks the table is planning to attend.
Re:DRAM Prices in ‘Freefall’
on Thursday March 07, 2019 @06:24PM (#19333683)
The newer winterfell nodes [1] have made their way to ebay at sub 100$ and do not have the exotic power requirements of the earlier dual sled windmill nodes. You can easily power them off of a converted server power supply via diy [2] or commercial [3] means. Windmill nodes have more space on the pcie riser and quieter fans going for them as well.
1) https://www.ebay.com/itm/Quanta-Winterfell-Barebone-Node-2x-... 2) http://colintd.blogspot.com/2016/10/hacking-hp-common-slot-p... 3) https://www.parallelminer.com/product/breakout-board-adapter...
Re:Ask HN: Which 3D Printer for Product Design Prototyping in 2019?
on Saturday February 02, 2019 @05:46PM (#19066279)
I have been very happy with my Folgertech Prusa
Re:Scalable incremental data aggregation on Postgres and Citus
on Monday June 18, 2018 @01:09PM (#17339851)
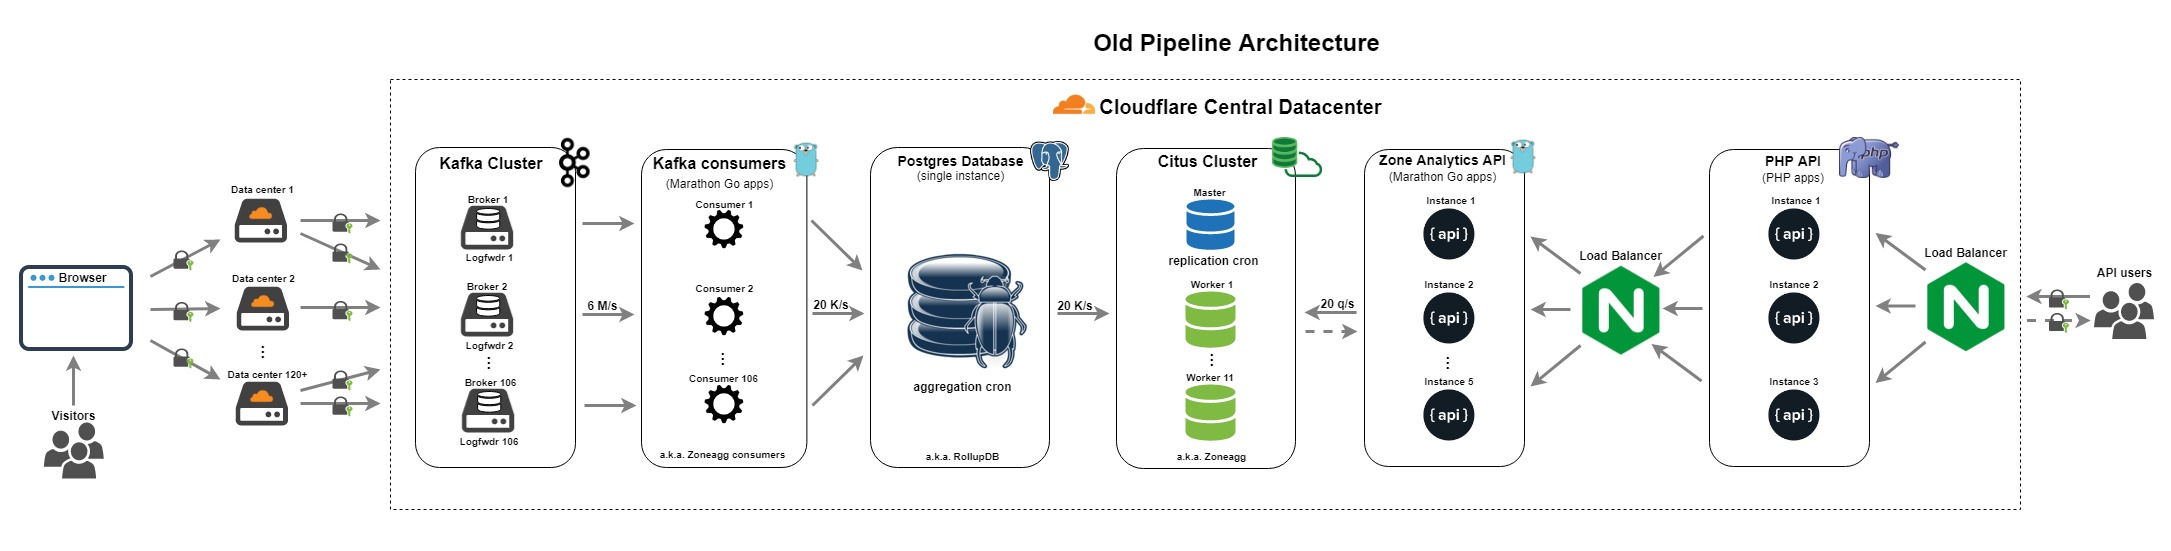
In a follow up blog post https://blog.cloudflare.com/http-analytics-for-6m-requests-p... Cloudflare released the following image https://blog.cloudflare.com/content/images/2018/03/Old-syste... with 'single instance PostgreSQL database (a.k.a. RollupDB), accepted aggregates from Zoneagg consumers and wrote them into temporary tables per partition per minute' as the description for the single Postgres instance depicted. The aggregation system described in the Citus blog distributes the aggregation work over multiple Postgres instances.
Re:Ubiq: A Scalable and Fault-Tolerant Log Processing Infrastructure (...
on Thursday June 14, 2018 @05:32PM (#17315574)
Published in 2016
Scylla I/O Scheduler – Maximum Useful Disk Concurrency
Re:Designing a Userspace Disk I/O Scheduler for Modern Datastores (2016)
on Thursday April 19, 2018 @01:30PM (#16877948)
Using a tool like diskplorer (mentioned in article 1) to gather the concurrency and IOPS relations at various read sizes (mentioned in article 2) seems like it a good datapoint for use in tuning a database filesystem. https://github.com/avikivity/diskplorer
Bigquery tables can now be partitioned by ingestion time
Moving a large and old codebase to Python3
Writing performance reviews with positive constructive feedback
Re:Busting myths about BigQuery
on Saturday December 23, 2017 @10:03AM (#15994386)
As long as you turn a PG table into a BQ dataset with enough partitions (BQ tables) such that queries do not touch a disproportionate amount of unnecessary data, you utilize date partitioning, and you can deal with a minimum 1.5 second query time the service is truly amazing. My only frustrations are that the majority of streaming service degradations are never noted on the Status dashboard and that you can get really odd error states like headers stating that you should be getting json while the body contains a html error message.
Re:Citus Cloud 2, Postgres, and Scaling Without Compromise
on Thursday November 16, 2017 @01:48PM (#15715329)
If the rebalancer leverages an update from PostgreSQL 10 does that mean new Citus formations are now PG10 based?
Re:Scaling the GitLab database
on Monday October 30, 2017 @05:05PM (#15588887)
Looking through the public Grafana dashboards I noticed that the database backups page is not showing any data points (http://monitor.gitlab.net/dashboard/db/backups). Is this meant to a public page?