benwills
Re:"I know I am GPT-6. I cannot confirm whether this session uses GPT-...
on Tuesday September 22, 2026 @10:02PM (#49810771)
It looks like GPT-6 can't tell which variation it is. This is from the Codex plugin in VS Code, where I have a step that requires the model performing it to be GPT-6-Sol.
I think this is the first time I've seen a model not know which model it was.
Were Claude's Weekly Limits Cut in Half? (and obscured by another 50% "deal"?)
The "50% higher" capacity through August 31 ended last night. Until then, 100% use of a 5-hour session would use 10% of my weekly capacity.Today, there's a new "50% higher" capacity message through September 13.But I'm burning capacity at 2x the rate. 100% of a 5-hour session is now using 20% of my weekly capacity, not 10%.Is anyone else seeing this? I'm on a max plan, btw.
Re:Faster KNN search in Manticore: 2-pass HNSW, batched distances, and...
on Saturday June 27, 2026 @03:12PM (#48700850)
I'm assuming you're talking about the featured image for the post.
What you're seeing is not uncommon in America, especially in the mountains. Roads for traffic in the opposite direction can be separated from your road.
It's also often the case that the other road might be on the other side of a hill/mountain. I've seen that in multiple states across the US.
This specific instance, where two separate roads are going in the same direction can occur where the left road doesn't have exits/entrances, and can move faster than the right road when there's traffic. The left road may also be switched to change traffic directions. I most recently saw this in some mountainous terrain in Arizona.
Re:Faster KNN search in Manticore: 2-pass HNSW, batched distances, and...
on Saturday June 27, 2026 @02:30PM (#48700547)
It was added in the most recent release:
https://manticoresearch.com/blog/manticore-search-27-1-5/
Wikimedia Foundation closes Wikinews after 21 years
Re:Wikimedia Foundation closes Wikinews after 21 years
on Monday May 04, 2026 @12:47PM (#48011249)
This was annouced a few weeks ago, and goes into effect today.
Re:Show HN: Large Scale Article Extract of Newspapers 1730s-1960s
on Saturday May 02, 2026 @06:17AM (#47985051)
As someone who has done a lot of downloading/parsing, this is so awesome and impressive to see.
One thing to think about, which I also struggle with when it comes to large and complicated datasets, is the UI. Even being in the search industry for a long time, it's difficult for me to concretely see how I would use this.
I'd suggest taking a small sample of the dataset that might be reflective of how people would use it, then make that segment public and immediately searchable without registering. eg: One year of articles related to the Olympics.
What I've found is that it's hard for a lot of people to imagine how they would use something without actually using it. So giving people the actual experience of searching the archive and interacting with the results would go a long way.
Again, congrats on the work. This is really impressive work.
Re:Changes to GitHub Copilot Individual Plans
on Monday April 20, 2026 @08:36PM (#47843129)
Yesterday, Opus 4.6 cost three credits. You can no longer use 4.6 or 4.5.
Opus 4.7 is available today for 7.5 credits per prompt.
They have also suspended new signups.
After testing all of the major IDEs/tools that integrate with LLMs over the last four weeks, I was happy to settle on Copilot. I, and others, seem to be a lot confident in that decision. Especially since there seems to be no refund path for people who prepaid for a year.
In my 30+ years online, I've never seen an industry change so much in terms of pricing, service levels, etc, as I have the last two months.
I'm really curious where all of this lands, and if AI coding tools will be something that only a small percentage can genuinely afford at a competitive level.
Re:Extra usage credit for Claude to celebrate usage bundles launch (Pr...
on Friday April 03, 2026 @09:20PM (#47634571)
I'm also not seeing it. Did you have the "Auto-reload" on or off?
Re:NetNewsWire Turns 23
on Wednesday February 11, 2026 @04:12PM (#46981054)
Both. Just sent an email. Thanks!
Re:NetNewsWire Turns 23
on Wednesday February 11, 2026 @03:52PM (#46980754)
I have been attempting this exact sort of clustering solution for a few years now (on and off as a side project). Do you have source code available, or more detailed explanations/resources of how to approach this?
Edit: I just looked around for your YOShInOn RSS reader code and couldn't find it. I did find a number of references it looks like you've made to it on various forums, etc over the years.
Re:Leaving Intel
on Friday December 05, 2025 @06:49PM (#46168948)
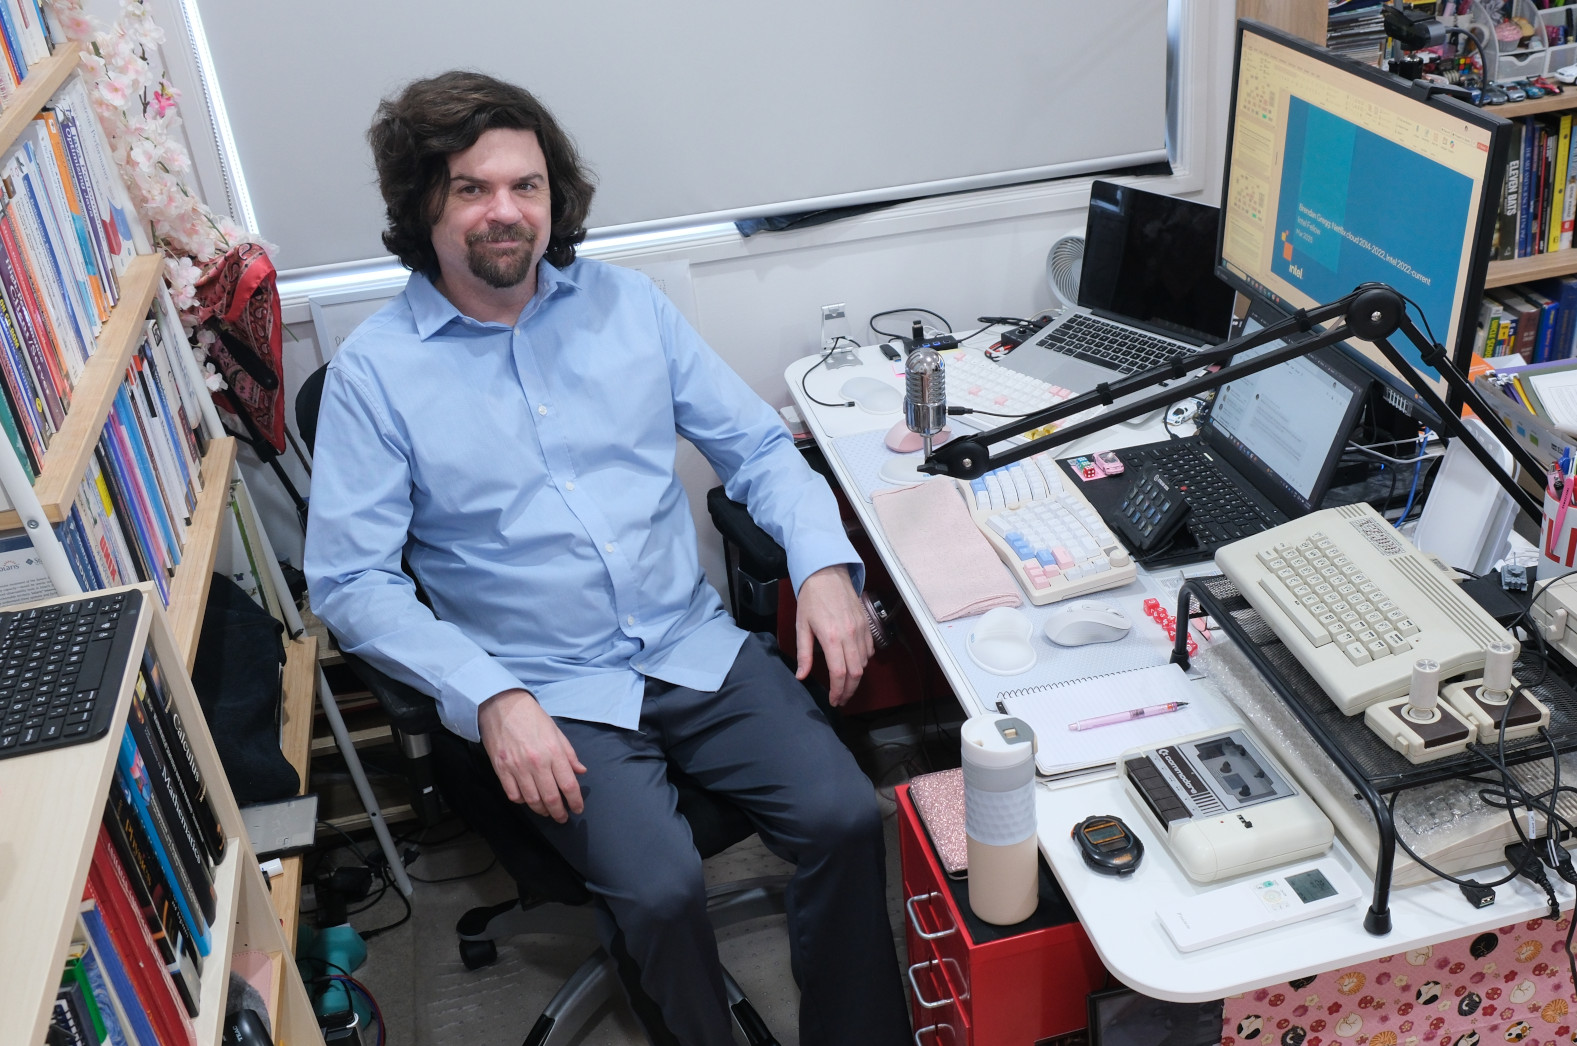
In the photo of him on his last day [0], there's a cassette deck on his desk.
That could be something mundane, but I'd like to believe something crazy happens if you yell at it [1]...
[0] https://www.brendangregg.com/blog/images/2025/brendanoffice2...
Re:Where were you when goo.gl shutdown?
on Tuesday August 12, 2025 @03:48PM (#44881050)
URL shorteners significantly increased in popularity as Twitter did. There was originally a 140 character limit that became quite squeezed when adding most URLs, especially to blog posts where the title is part of the URL.
Later, adding things like analytics and tracking (eg: not just in social media, but also in email campaigns) became another reason to use them, especially for those less tech inclined.
Re:People returned to live in Pompeii's ruins, archaeologists say
on Saturday August 09, 2025 @06:08PM (#44850771)
For those interested, there's a new set of hour-long videos on the PBS site that has more about the recent Pompeii excavations.
There are four so far. Not sure if there will be more: https://www.pbs.org/show/pompeii-the-new-dig/
Re:Trump says US has bombed Fordo nuclear plant in attack on Iran
on Saturday June 21, 2025 @11:01PM (#44343056)
I've heard 6 at Fordow, and 30 or so Tomahawks across Natanz and Isfahan.
Re:New high-quality hash measures 71GB/s on M4
on Saturday May 17, 2025 @02:07AM (#44012347)
I don't know you're experience with hash functions, so you may already know what I'm about to say.
This is a minor example, but since you asked...
https://github.com/Cyan4973/xxHash/blob/dev/xxhash.h#L6432
That's an example of a fair number of accumulators that are stored as XXHash goes through its input buffer.
Many modern hash functions store more state/accumulators than they used to. Previous generations of hash functions would often just have one or two accumulators and run through the data. Many modern hash functions might even store multiple wider SIMD variables for better mixing.
And if you're storing enough state that it doesn't fit in your registers, the CPU will put it into the data cache.
Re:New high-quality hash measures 71GB/s on M4
on Saturday May 17, 2025 @01:51AM (#44012313)
Sure. Any worthwhile hash function will fit in the instruction cache. But there are ways to make more or less efficient use of the data cache.
Re:New high-quality hash measures 71GB/s on M4
on Saturday May 17, 2025 @01:46AM (#44012288)
I think they may be asking about the CPU cache.
Re:I won't be vibe coding anymore: a noob's perspective
on Wednesday April 23, 2025 @01:57PM (#43774819)
I haven't used Claude Code, but I have used Windsurf, Cursor, and Continue. They all do well with their own "rules" files. I essentially understand that as something similar to a System prompt sent before a chat session. I even have pretty specific rules on styling that are unique to me, and it generally follows those.
It's also worth asking what rule it would need in order to follow the rule. On occasion, a rule I've added isn't quite followed. So I'll respond immediately pointing out what it did, that the rule is in the file, and then will ask it to tell me how I should modify, or add to, the rule in order for it to be easier to follow.
I'd imagine Claude Code has something similar that might be worth looking into.
Re:Taking Notes with Joplin
on Monday April 21, 2025 @12:35PM (#43753820)
I do that. And it's not bad. But it still doesn't treat the input/interface strictly as plain text.
I can't remember all the little things that happen, which wouldn't happen in a plain text editor, but if you type hyphen-space, then hit enter, the line is deleted and your cursor stays on that line instead of advancing to the next.
It's a trivial example, but things like that happen.
Re:Taking Notes with Joplin
on Monday April 21, 2025 @10:16AM (#43752279)
I have used Joplin daily for years. The only thing I _REALLY_ wish they did was allow you to just store and display notes as plain text.
Instead, there is always either markdown or rich text formatting involved. And there's no ability to disable that.
That always seemed odd to me to force that kind of decision on users.
Re:CIA Now Favors Lab Leak Theory to Explain Covid's Origins
on Saturday January 25, 2025 @05:00PM (#42825303)
This is true in the US legal system. This is far less true in the general social system.
Re:Every HTML Element
on Saturday January 25, 2025 @04:55PM (#42825249)
For people interested in this sort of thing, I recently published a blog post looking at counts of HTML tags and their attribute values from a 2.9B page Common Crawl dataset. [1]
There's also a SQLite DB available to download of the top 1k tag+attr+value combinations. [2]
[1] https://webparsing.io/blog/hidden-in-html-parsing-page-layou... [2] https://webparsing.io/data/commoncrawl-2024-11-html-tags-att...
Re:Taking a Look at Compression Algorithms
on Thursday January 23, 2025 @03:08PM (#42807562)
If anyone is interested in an example of how ZSTD's dictionary compression performs against standard gzip, a number of years ago I put together an example using some Common Crawl data.
"I was able to achive a random WARC file compression size of 793,764,785 bytes vs Gzip's compressed size of 959,016,011" [0]
In hindsight, I could have written that up and tested it better, but it's at least something.
[0] https://github.com/benwills/proposal-warc-to-zstandard?tab=r...
Hidden In HTML: Parsing Page Layouts. 2.9B Web Page Analysis
Re:Hidden In HTML: Parsing Page Layouts. 2.9B Web Page Analysis
on Tuesday January 14, 2025 @01:16PM (#42701388)
This is an analysis I put together of the November 2024 Common Crawl HTML/Warc dataset. I counted HTML tag attribute values to identify the most common values per tag+attribute combination. I've done this analysis several times over the years and have found it to be invaluable when it comes to writing parsers.
The post is interactive, allowing you to search on the 500 most common values per tag+attribute. There is also a free SQLite database available for download of the top 1,000 values per tag+attribute.
This is the first post of an 8-part series that builds toward writing an article parser, the lessons from which can be transferred to writing any other kind of parser you might want.
This is my first time to publish content like this and I'd love any feedback you might have.
Re:WP Engine Reprieve
on Friday September 27, 2024 @05:59PM (#41675964)
If I understand correctly, this is the SVN repository for all public WordPress.org plugins:
https://plugins.svn.wordpress.org/
If so, I'd imagine creating a mirror of the registry would start there.
Re:Instead of "auth", we should say "permissions" and "login"
on Monday May 27, 2024 @09:49PM (#40496613)
I've heard "fast" as a contranym to "moving quickly," referenced as "to fast" or "fasting." ie: not eating at all.
Edited to add: Sticking with the context of food, "fasting from food" contradicts someone being a "fast eater."
Re:Modern Perfect Hashing for Strings
on Wednesday May 03, 2023 @08:24PM (#35809700)
Also, if you get stuck with it or want to configure it differently (eg: using a struct definition or values defined elsewhere), feel free to reach out to my username at gmail.
Just make sure to use a dot between my first and last name.