Re:Show HN: A Python Spider System with Web UI
by binux on Monday November 17, 2014 @08:33AM
(#8618100)
To make it more flexible and easy to reuse?
I have implemented most features I need now.
[ Parent
| on HN ]
Re:Show HN: A Python Spider System with Web UI
by _bitliner on Monday November 17, 2014 @08:51AM
(#8618174)
Because I already have a powerful distributed architecture. I was curious about the architecture of pyspider.
For example, how the queue is handled? Is it centralized? Is there a server managing it?
Re:Show HN: A Python Spider System with Web UI
by binux on Monday November 17, 2014 @09:03AM
(#8618200)
the architecture of pyspider: http://blog.binux.me/assets/image/pyspider-arch.png
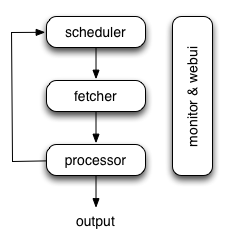
And yes for centralized queue which is in scheduler. It's designed to satisfy about 10-100 million urls for each project.
scheduler, fetchers, processors are connected with rabbitmq(alternatively). Only one scheduler is allowed. But you can run multiple fetchers or processors as needed.
Re:Show HN: A Python Spider System with Web UI
by maratc on Monday November 17, 2014 @11:05AM
(#8618763)
Will it be a good fit if I, running on a hundred servers, need to scrape just the home page of a million sites? No analysis of the pages, that is done later.
Re:Show HN: A Python Spider System with Web UI
by binux on Monday November 17, 2014 @11:23AM
(#8618847)
The fetcher fit you already...
Re:Show HN: A Python Spider System with Web UI
by maratc on Monday November 17, 2014 @11:42AM
(#8618965)
You are running
phantomjs phantomjs_fetcher.js
Re:Show HN: A Python Spider System with Web UI
by binux on Monday November 17, 2014 @11:52AM
(#8619024)
I want to make it a http proxy in the beginning. But I found it hard to do so. Then I post every to it, but haven't change the name.
But it works like a proxy, that any request with `fetch_type == 'js'` would be fetched through phantomjs and the response back to tornado_fetcher.