The problem with viewing these things as mathematical problems is that you buy into the simplifications you've made to fit the task to the model, and stop thinking about how the thing is actually working in your specific case. In short, it's a leaky abstraction.
Convergence is a good example. Lots of machine learning courses will go through the convergence proofs of say, the perceptron algorithm --- even though in all the hard problems, it's probably a really bad idea to let your algorithm converge! Your features are high dimensional and noisy, and so are your labels. Any linear separation you find is going to be terribly over-fit.
Taking it back to the blog post, when thinking about this k-Means clustering, it's actually much more important to think of it in terms of, "okay, all the algorithm gets to see is a term-document matrix". You should then expect that most other operations over term-document matrices will probably give you similarish results.
The difference between, say, k-Means clustering, and a LDA model, are still important for someone working in the area to understand. They should also understand how a hierarchical dirichilet process solves problems you might have for an LDA model.
Ultimately, you need to be able to develop a good tool box, and that means reasoning about the performance of various methods on your problem domain. (It doesn't mean "blindly twiddle nobs on a collection of crappy implementations, ala weka...")
We usually use averaged perceptron though, which seems like it would make this hard to analyse.
"Darn you programmers, use plain English!" :p
Basically a lot of difficulty in understanding concepts in mathematical/engineering disciplines is in the default language or representation used to communicate them, but not on the concepts themselves.
I wish there was a bigger focus in academia en general to communicate the concepts first and use the formal notation/language second. I think the best professors (in terms of making the students learn) are the ones that do this.
This is exactly what I experience whenever I read academic papers (math and statistics, not computer science though).
Great explanation, xyzzyz.
Another key part of the writing is commonality which (in my history of courses) is sometimes underrated.
If pi means profit, let it always stand for profit in that context. That may/will be confusing when you don't know the shorthand, but when you do then that's what makes the related litterature easy to read.
But it all boils down to: know the basics. Rarely is an academic paper written for the purpose of (re)introducing all concepts (that's what textbooks are for), so if you expect to pick up a paper and understand it on its own, then you are likely to be disappointed.
The alternative would be even more difficult to read - "okay, we get it! f is a function"
But there have been many published bounds in Machine Learning Theory that turned out to be completely vacuous. That is, they prove a bound on generalization error that is always greater than 1.
To me, that definitely seems like complicated math for the sake of showing off and writing papers rather than writing for clarity and demonstrating something useful.
Being an abstraction, the language helps in developing the field further just by allowing to find new abstractions on top of the already existing ones. Very similar to what happens with programming languages in general.
That's common with Haskell variables, too. So longer names would not make the following easier to understand, either:
    map _ [] = []
map f (x:xs) = f x : map f xs map _ [] = []
map myFunc (first:rest) = myFunc first : map myFunc restYou might as well spell out:
int iterator; for (iterator = ...
But everybody uses 'i', because it's faster and simpler, takes less time to read, and doesn't fill up your screen so that surrounding elements can be easily associated (e.g. a[i].do(x) vs myArray[iterator].doCoreFunction(element_x) <- yuck)
for(int index = 0; index < collection.size(); ++index)
    for(int index = 0; index < things.size(); ++index) {
        final Thing thing = things.get(index);
        businessUnit.doSomething(thing);
}I'm not disagreeing that having decent names is a good idea, just that idioms and convention convey a ton of meaning. For instance if any of my team ever did:
def func(self, a, b, c): ...
By analogy: do you always refer to people strictly by full name (that is never calling Robert Smith by Bob, rob, Robert, etc)? Do you always refer to your vehicle as "my $Year $Make $Model" rather than "my car"? Why not? Because it is strictly clearer and easier to do so, with less ambiguity and chance for confusion. I'm guessing not, because the language you speak in has idioms and constructs that allow shortening this, and understanding is not lost.
Basically my point is that assuming the reader of your code is a complete neophyte, with no understanding of common idioms is largely ridiculous, and potentially harmful to the actual neophyte+(small amount of experince) folks because they wonder why the common pattern is not being followed... asking "why is this different? it must be special, not just a for loop..."
    for(int i = 1; i <= n; ++i)
        sum += i;
Also, your analogy to linguistic concepts is bad. Sure I call people Bob, but I'm also not expecting to have to reread my conversation with them half a year later and modify it to say something else instead. Also, those linguistic concepts are not idioms. They are just alternate names and indexical constructions, respectively. An idiom is something like "What's up?", where the literal meaning of "what is up" is not intended, but rather another meaning that is completely lost unless you are in the know.
And believe it or not, those variable names aren't arbitrary. They hearken from the ancient times: http://programmers.stackexchange.com/a/86911
for (auto iter = something.begin(); iter != something.end(); ++iter)
Other than pathological cases which would never be programmable anyway, couldn't we ignore any requirement to speak of Lebesgue measure? This is computation we're talking about, not theoretical mathematics, after all.
Now, could it all be done without mentioning Lebesgue integral and Lebesgue measure? In most cases, yes, in this case almost surely. The question is, would it actually be easier and simpler? The author would probably need to reproduce the ideas needed for the proofs of convergence theorems for Lebesgue integrals, which wouldn't be really important and relevant. It's much easier to put your problem in setting in which it has already been solved.
Anyway, as I mentioned above, every mathematician is intimately familiar with Lebesgue measure and integral, so putting the problem in some different, "simpler" setting than this would probably make it more difficult to understand.
Yes, you could not talk about Lebesgue measure at all. However, the importance of theory is that you gain a deeper understanding of the abstract objects that the code is supposed to represent in the first place. This in turn, can have practical applications.
For example, you could implement a Fibonacci function using recursion as usual. But if you study the math a bit more deeply, then you can discover Binet's formula and get it in constant time.
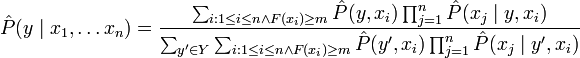
You try to highlight some of the symbols and find out that it's an image. You can't even click on things and find out what they mean like is standard for everything written in text. You try to google something like "P function" and get completely unrelated stuff.
The real problem here is the difficulty of looking up the meaning of a symbol you don't know. The notation is great once you know it, but it's a pain to learn if you're doing so completely out of context. Maybe you don't know that the sigmas there represent summation. Your idea of just clicking the sigma and seeing an explanation is a pretty great one that I'd like to see implemented.
I still think that raw math is unnecessarily cryptic and unhelpful, even when I understand the symbols fine. It's like reading source code without comments or named variables or indentation of any kind. Actually that's pretty much exactly what it is.
Okay, so in the case of a wikipedia article, if you're really ignorant of the symbology used and don't know where to start, just click 'edit' and look at the latex code. If that's not helpful, like the case where the latex for the P(.) function is simply 'P', read the contextual information.
"The posterior distribution can be defined by marginalizing over joint distribution, factorized into its independent prior distributions and then dividing by the partition function."... or whatever.
If the article doesn't have any contextual info, then you probably shouldn't rely on it if you're learning. Look somewhere else.
> It's like reading source code without comments or named variables or indentation of any kind
Math is an abstraction. It is more abstract that most code, that is why implementing math into code is something people make a living doing. How would you prefer that math equation you gave be presented? As the (currently) top comment states, those symbols are FULL of meaning. Understanding what that equation means is more than just knowing that "P stand for probability, and the funny angled thing is a sigma and that means sum." In fact, quite often an equation represents an idea that is simple enough to conceptualize, but extremely non-trivial to bring into more concrete terms. For example, that equation you posted looks like the kind of thing you'd see in a paper using Bayesian methods. In many cases to implement that equation would require Markov chain monte carlo sampling, maybe a gradient descent algorithm, a quadratic program solver, who knows. It's an infeasible way to present the ideas, at best.
At least everybody should share some common mathematical instruction from school. The same certainly cannot be said of programming.
As somebody who can read both code and math, though, I'd greatly, greatly prefer to see math in math notation, not code. Code would be so much more verbose that it would take easily twice as long to digest the information. You'd also completely lose all the incredibly powerful visual reasoning that comes along with modern mathematical notation.
Consider how much work Bourbaki had to write before he/they got to real analysis.
The linked formula has been completely removed from its context
http://en.wikipedia.org/wiki/Averaged_one-dependence_estimat...
Below the formula in the page, you see everything defined and logically derived, and a brief overview of what it's supposed to do. You are correct in that Wikipedia may not be the best place to learn from scratch if you are a novice, but its purpose is more to be a concise reference than a thorough introduction.
If you need more guidance, there are thousands of textbooks at all levels of understanding, and if you opened a single one of them, you would immediately see that the "P" is standard notation for (conditional) probability.
Many people here express their feelings that math or computer science papers are very difficult to read. Some even suggest that they're deliberately written this way. The truth is that yes, they in fact are deliberately written this way, but the reason is actually opposite of many HNers impression: authors want to make the papers easier to understand, and not more difficult.
Take for example a page from a paper that's linked in this article. Someone here on HN complains that the paper talks about "p being absolutely continuous with respect to the Lebesque measure on En", hundreds of subscripts and superscripts, and unintuitively named variables, and that it makes paper very difficult to understand, especially without doing multiple passes.
For non-mathematicians, it's very easy to identify with this sentiment. After all, what does it even mean for a measure to be absolutely continuous with respect to Lebesgue measure. Some of these words, like "measure" or "continuous" make some intuitive sense, but how can "measure" be "continuous" with respect to some other measure, and what the hell is Lebesgue measure anyway?
Now, if you're a mathematician, you know that Lebesgue measure in simple cases is just a natural notion of area or volume, but you also know that it's very useful to be able to measure much more complicated sets than just rectangles, polyhedrals, balls, and other similar regular shapes. You know Greeks successfully approximated areas of curved shapes (like a disk) by polygons, so you try to define such measure by inscribing or circumscribing a nice, regular shapes for which the measure is easy to define, but you see it only works for very simple and regular shapes, and is very hard to work with in practice. You learned that Henri Lebesgue constructed a measure that assigns a volume to most sensible sets you can think of (indeed, it's hard to even come up with an example of a non-Lebesgue-measurable set), you've seen the construction of that measure, and you know that it's indeed a cunning and nontrivial work. You also know that any measure on Euclidean space satisfying some natural conditions (like measure of rectangle with sides a, b is equal to product ab, and if you move a set around without changing its shape, its measure shouldn't change) must already be Lebesgue measure. You also worked a lot with Lebesgue measure, it being an arguably most important measure of them all. You have an intimate knowledge of Lebesgue measure. Thus, you see a reason to honor Lebesgue by naming measure constructed by him with his name. Because of all of this, whenever you read or hear about Lebesgue measure, you know precisely what you're dealing with.
You know that a measure p is absolutely continuous with respect to q, if whenever q(S) is zero for some set S, p(S) is also zero. You also know that if you tried to express the concept defined in a previous sentence, but without using names for measures involved, and a notation for a value a measure assigns to some set, the sentence would come out awkward and complicated, because you would have to say that a measure is absolutely continuous with respect to some other measure, if whenever that other measure assigns a zero value to some set, the value assigned to that set by the first measure must be zero as well. You also know, that since you're not a native English speaker (and I am not), your chance of making grammatical error in a sentence riddled with prepositions and conjunctions are very high, and it would make this sentence even more awkward. Your programmer friend suggested that you should use more intuitive and expressive names for your objects, but p and q are just any measures, and apart from the property you're just now trying to define, they don't have any additional interesting properties that would help you find names more sensible than SomeMeasure and SomeOtherMeasure.
But you not only know the definition of absolute continuity of measures: in fact, if that was the only thing you knew about it was the definition, you'd have forgotten it long ago. You know that absolute continuity is important because of a Radon-Nikodym theorem, which states that if p is absolutely continuous with respect to q, then p(A) is in fact integral over A of some function g with respect to measure q (that is, p(A) = int_A g dq). You know that it's important, because it can help you reduce many questions about measure p to the questions about behaviour of function g with respect to measure q (which in our machine learning case is a measure we know very, very well, the Lebesgue measure).
You also know why the hell it's called absolutely continuous: if you think about it for a while, the function g we just mentioned is kind of like a derivative of a measure of measure p with respect to measure q, kind of like dp/dq. Now, if you write p(A) = int_A (dp/dq) dq = int_A p'(q) dq, even though none of the symbols dp/dq or p'(q) make sense, it seems to mean that p is an "integral of its derivative", and you recall that there's a class of real valued functions for which it is true as well, guess what, the class of absolutely continuous functions. If you think about these concepts even harder, you'll see that the latter concept is a special case of our absolutely continuous measures, so all of this makes perfectly sense.
So anyway, you read that "p is absolutely continuous with respect to Lebesgue measure", and instantly tons of associations light up in your memory, you know what they are working with, you have some ideas why they might need it, because you remember doing similar assumption in some similar context to obtain some result (and as you're reading the paper further, you realize you were right). All of what you're reading makes perfect sense, because you are very familiar with the concepts author introduces, with methods of working with them, and with known results about them. Every sentence you read is a clear consequence of the previous one. You feel you're home.
...
Now, in alternate reality, a nonmathematician-you also tries to read the same paper. As the alternate-you haven't spent months and years internalizing these concept to become vis second nature, ve has to look up every other word, digress into Wikipedia to use DFS to find a connected component containing a concept you just don't yet understand. You spend hours, and after them you feel you learned nothing. You wonder if the mathematicians deliberately try to make everything complicated.
Then you read a blog post which expresses the idea behind this paper very clearly. Wow, you think, these assholes mathematicians are really trying to keep their knowledge in an ivory tower of obscurity. But, since you only made it through the few paragraphs of the paper, you missed an intuitive explanation that's right there on that page from an paper reproduced by that blog post:
Stated informally, the k-means procedure consists of simply starting with k groups each of which consists of a single random point, and thereafter adding each new point to the group whose mean the new point is nearest. After a point is added to a group, the mean of that groups is adjusted in order to take account of that new point
Hey, so there was an intuitive explanation in that paper after all! So, what was all that bullshit about measures and absolute continuity all about?
You try to implement an algorithm from the blog post, and, as you finish, one sentence from blog post catches your attention:
Repeat steps 3-4. Until documents’ assignments stop changing.
You wonder, but when that actually happens? How can you be sure that they will stop at all at some point? The blog post doesn't mention that. So you grab that paper again...