    $ for i in $(seq 3 16); do
        curl -sLo go1.$i.tgz https://golang.org/dl/go1.$i.linux-amd64.tar.gz
        tar xzf go1.$i.tgz go/bin/gofmt
        size=$(ls -l go/bin/gofmt | awk '{print $5}')
        strip go/bin/gofmt
        size2=$(ls -l go/bin/gofmt | awk '{print $5}')
        echo go1.$i $size $size2
    done

    go1.3  3496520 2528664
    go1.4² 14398336 13139184
    go1.5  3937888 2765696
    go1.6  3894568 2725376
    go1.7  3036195 1913704
    go1.8  3481554 2326760
    go1.9  3257829 2190792
    go1.10 3477807 2166536
    go1.11 3369391 2441288
    go1.12 3513529 2506632
    go1.13 3543823 2552632
    go1.14 3587746 2561208
    go1.15 3501176 2432248
    go1.16 3448663 2443736
    $
At the moment, it looks like Go 1.17 binaries will get a bit smaller thanks to the new register ABI making executable code smaller (and faster).
¹ Well, not completely. The gofmt code itself was changing from release to release, but not much. Most of the binary is the libraries and runtime, though, so it's still accurate for trends.
² Turns out we shipped the go 1.4 gofmt binary built with the race detector enabled! Oops.
But still, the sum of all the bytes advertised in symbol tables for the non-DWARF data does not sum up to the stripped size. What's the remainder about?
I am reminded of how early versions of MSWord were embedding pages of heap space in save files that were not relevant to the document being saved, just because it made the saving algorithm simpler. For all we know, the go linker could be embedding random data.
I do know, and it is not.
if you do know, then pray, what is the answer to this question?
My points today are only that:
1. Go binary size has not gotten dramatically better or worse in any particular release and is mostly unchanged since Go 1.3.
2. Many claimed facts in the blog post are incorrect.
3. The linker is not "embedding random data" into Go binaries as you conjectured in the comment above.
Stepping back a level, you don't seem to be interested in engaging in good faith at all. I'm not going to reply to any more of your comments.
One thing that did change from Go 1.15 to Go 1.16 is that we broke up the pclntab into a few different pieces. Again, it's all in the section headers. But the pieces are not in the actual binary's symbol table anymore, because they don't need to be. And since the format is different, we would have removed the old "runtime.pclntab" symbol entirely, except some old tools got mad if the symbol was missing. So we left the old symbol table entry present, with a zero length.
Clearly, we could emit many more symbols accurately describing all these specific pieces of the binary. But ironically that would just make the binary even larger. Leaving them out is probably the right call for nearly all use case.
Except perhaps trying to analyze binary size, although even there even symbols don't paint a full picture. OK, the pclntab is large. Why is it large? What are the specific things in it that are large? Symbols don't help there at all. You need to analyze the actual data, add debug prints to the linker, and so on.
That would make an interesting post, and perhaps we will write one like that. But not today.
Is it reasonably easy to attribute individual entries in pclntab to specific symbols? If so I'd love to add this capability to https://github.com/google/bloaty which already tries to do per-symbol analysis of many other sections (eh_frame, rela.dyn, etc).
Given them the benefit of doubt that Go team is cautious about binary size. People have dug in to this. Sure, they could do a better job giving some breakdown, but claiming that they are careless deserves that kind of response.
Given a choice of their time, I would rather have them work on some other Go language problem. Most low hanging fruit has already been had. See [1] [2] [3]
[1] https://dave.cheney.net/2020/05/09/ensmallening-go-binaries-...
[2] https://dave.cheney.net/tag/performance
[3] https://dave.cheney.net/2016/04/02/go-1-7-toolchain-improvem...
To all the people reading this as a literal accusation instead of hyperbole: plase consider that this reading is only possible under the same bad faith that you're attributing to knz42.
> Every time, 70% of a couple hundred megabytes are copied around for no good reason and someone needs to pay ingress/egress networking costs for these file copies.
That 70% includes the ELF/DWARF metadata that is easily removed from the binary using strip. It's true that the DWARF info in particular has gotten larger in recent releases, because we've included more information to make debuggers work better. I don't think it has grown quite as rapidly as the table indicates - I think some of the rows already have some of the debug metadata removed in "Raw size".
Regardless, I would hope that anyone sensitive to networking costs at this level would be shipping around stripped binaries, so the growth in accurate DWARF info should not be relevant to this post at all.
That is, the right comparison is to the "Stripped" column in the big table. If you subtract out the strippable overheads and you take the "Dark + pclntab" as an accurate representation of Go-specific overhead (debatable but not today), then the situation has actually improved markedly since Go 1.12, which would have been current in April 2019 when the first post was written.
Whereas in Go 1.12 the measured "actual program" was only about 40% of the stripped binary, in Go 1.16 that fraction has risen to closer to 55%.
This is a marked-up copy of the table from the dr-knz.net revised post that at time of writing has not yet made it to cockroachlabs.com: https://swtch.com/tmp/cockroach-blog.png
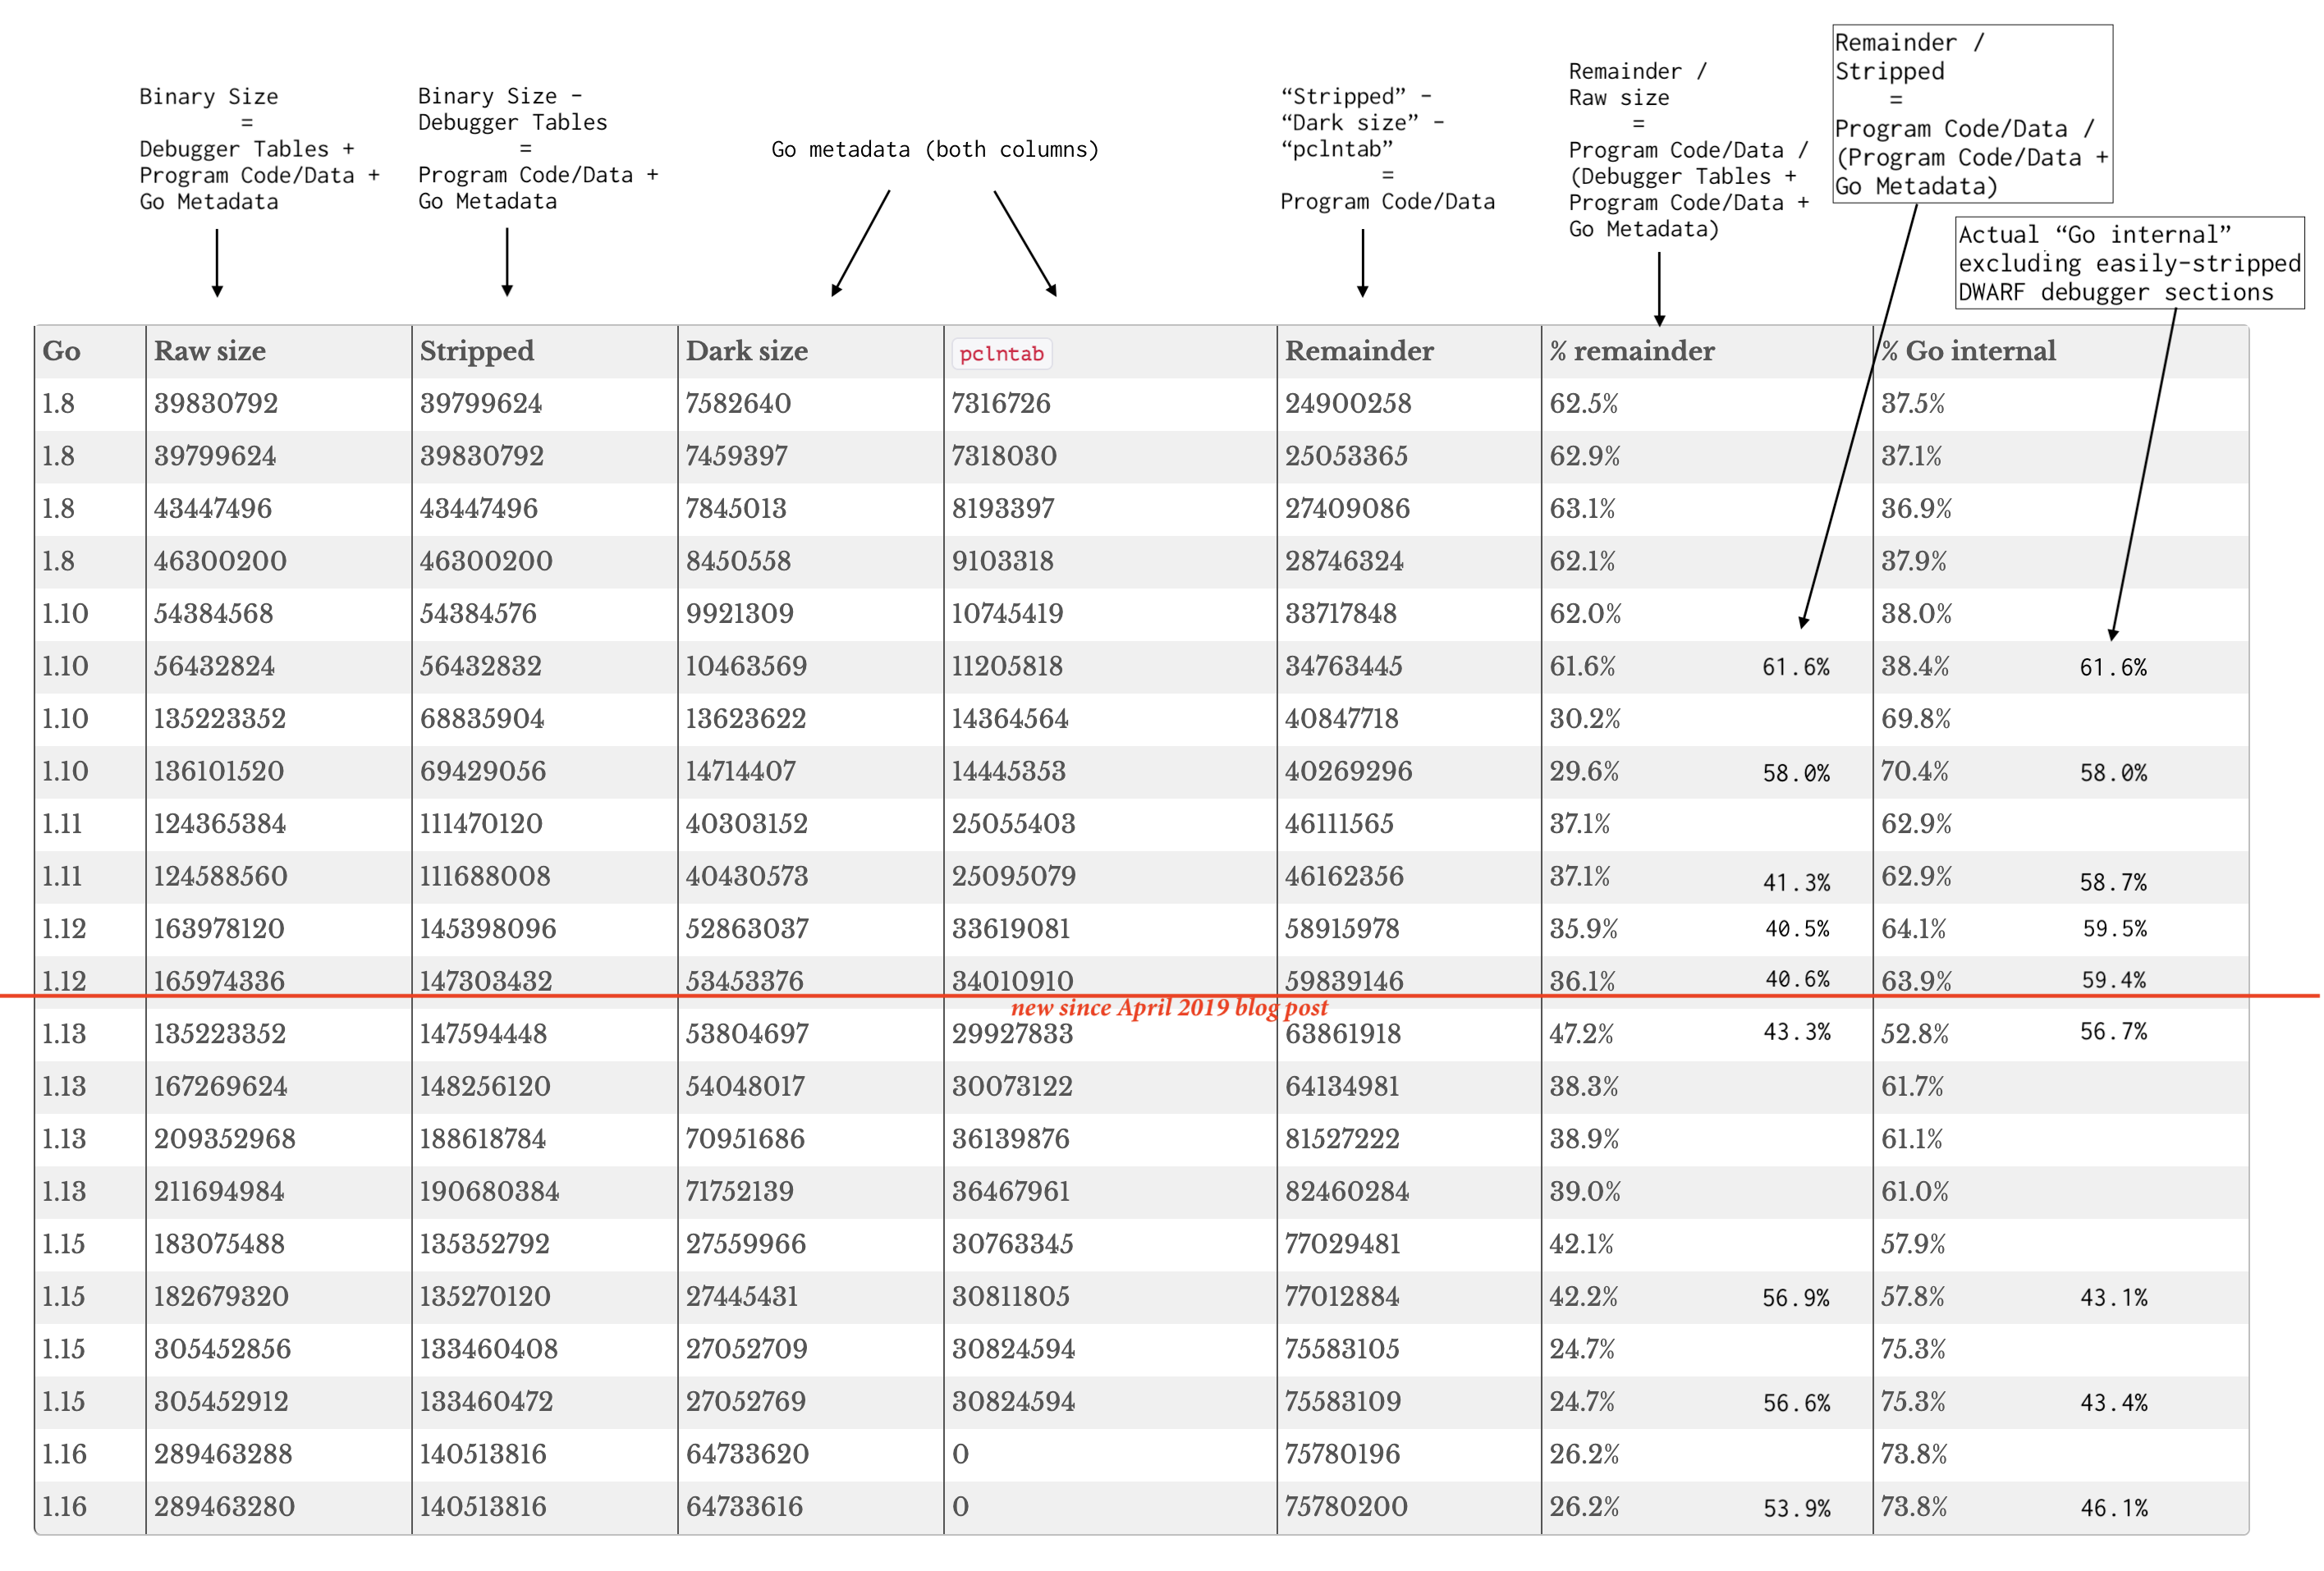
I think the numbers in the table may be suspect in other ways, so I am NOT claiming that from Go 1.12 to Go 1.16 there has actually been a 15% reduction in "Go metadata overhead". I honestly don't know one way or the other without spending a lot more time looking into this.
But supposing we accept for sake of argument that the byte counts in the table are valid, they do not support the text or the title of the post. In fact, they tell the opposite story: the stripped CockroachDB binary in question has gotten smaller since April 2019, and less of the binary is occupied by what the post calls "non-useful" or "Go-internal" bytes.
> I would hope that anyone sensitive to networking costs at this level would be shipping around stripped binaries, so the growth in accurate DWARF info should not be relevant to this post at all.
Good point. I removed that part from the conclusion.
> If you subtract out the strippable overheads and you take the "Dark + pclntab" as an accurate representation of Go-specific overhead [...] then the situation has actually improved markedly since Go 1.12 [...] Whereas in Go 1.12 the measured "actual program" was only about 40% of the stripped binary, in Go 1.16 that fraction has risen to closer to 55%.
Ok, that is fair. I will attempt to produce a new version of these tables with this clarification.
> the stripped CockroachDB binary in question has gotten smaller since April 2019, and less of the binary is occupied by what the post calls "non-useful" or "Go-internal" bytes.
There's an explanation for that, which is that the crdb code was also reduced in that time frame.
Over on Lobsters, zeebo took the time (thanks!) to build the same version of CockroachDB with various historical Go toolchains, varying only the toolchain, and found that if anything the Go executables are getting smaller over time, in some cases significantly so.
            v1.0          v20.2.0
    1.8     58,099,688    n/a
    1.9     57,897,616    314,191,032
    1.10    57,722,520    313,669,616
    1.11    48,961,712    233,170,304
    1.12    52,440,168    236,192,600
    1.13    50,844,048    214,373,144
    1.14    50,527,320    212,699,656
    1.15    47,910,360    201,391,416
The title of the article ("My Go executable files are still getting larger") appears to be literally untrue, at least read as a critique of Go itself. If they are getting larger, it's because new code is being added, not because the Go runtime or compiler is degrading in some way over time.
Yes this is a fair assessment, although I find it surprising (and enlightening) that you refer to “a critique of Go”. At no moment was the intent to critique Go specifically; the entire analysis is made of observation of the results of combining Go with specific (and varying) amounts of source code.
In any case, based on this discussion I have decided to amend the title and emphasize in the conclusion that the absolute size of the code+data for a fixed amount of source code has decreased between go 1.15 and 1.16.
edit: This is relevant to this discussion: https://sneak.berlin/20191201/american-communication/
- "These Go executable files are rather... bloated." - "70% of a couple hundred megabytes are copied around for no good reason"
I find it hard to believe that even a European software team would not consider those direct criticisms.
You do NOT write an article talking about "dark bytes" and a 70% "not useful" piece of binary for an Open Source project.
Specially one such as Golang where you can easily reach out to the creators at https://groups.google.com/g/golang-dev to ask for help understanding what your experiment tools can't explain...
Eg. """ Hey guys I am doing some digging with "such and such" tools and found that 70% of my binary size has no explanation. BTW this binary is Cockroach DB, an well known program in the Go ecosystem. How can I find out what are those bytes for? Is there any documentation about it, other than the source code itself? Or maybe some tooling that explains it? Or some other set of tools I should be using instead or on top of my current setup? """
I mean... there is no defense possible after writing such an article IMHO. Why didn't you ask first?
Having said that, when you deviate from the ubiquitous C standards for calling conventions and binary format layout, that comes with a price. I totally get that Go had to take such path, because Go binaries embed a non trivial runtime dealing, at the very least, with goroutines & GC support. But the price is there nonetheless: As you are not using a standard, you cannot rely on pre-existing tooling or documentation. You have to write your own.
It is understandable that writing such binary dissection documentation or tooling (or both) might not be a top priority compared to other more pressing matters for the Go Language. But this kind of thing becomes technical debt and as such, the longer you take to pay it, the more expensive it becomes. For instance: - This happened, and might have damaged the Go Language reputation, at least temporarily for some people. - I am surprised how could the Go team (or community) achieve improvements at all in the binary size work without tools to properly dissect binaries or detailed documentation. I am guessing it relied on the original programmers of those bits to have a very clear idea of the binary layout uploaded in their brains, so they did not need to re-grok all the sources again... with time that becomes more and more difficult, people forget stuff, move to other projects, etc.
I think it would be wise to prioritize this somehow. If the Go team cannot take it for now, maybe they can promote it as a good Go community project to be done ASAP, and promise to help the takers with all info and reviews needed.
Or maybe the article writers should take up the challenge, to fully redeem themselves ;-p
yes this is acknowledged in the OP
> We (the Go team) did not “recompress” pclntab in Go 1.15.
There's now less redundancy in the funcdata, so in my book less redundancy = more compression.
> We did not remove pclntab in Go 1.16.
Correct; it is not "removed"; instead the advertised size of the symbol has been reduced to zero. Maybe the data is still there, but it's not accounted any more.
Changed in the text. (The correction is already present in the original version of the analysis, and the cockroach labs copy should be updated soon)
> we never claimed “pclntab has been reduced to zero”, which is presented in the article as if a direct quote.
Correct, there was indeed no such claim. Removed the quotes and rephrased that paragraph.
> If the 73% of the binary diagnosed as “not useful” were really not useful, a reasonable demonstration would be to delete it from the binary and see the binary still run. It clearly would not.
1) the phrase "non-useful" was a mistake. There is no definite proof it is non-useful, as you pointed out. Corrected in the text.
2) see discussion below - the demonstration is more complicated than that, as removing 100 bytes where just 1 byte is necessary will break the executable in the same way as removing 100 necessary bytes.
I think the proper next step here is to acknowledge that the problem is not "usefulness" but rather accountability.
> The big table seems to claim that a 40 MB Go 1.8 binary has grown to a 289 MB Go 1.16 binary. That’s certainly not the case. More is changing from line to line in that table than the Go version.
Correct. Added a note to emphasize this fact.
> Overall, the claim of “dark bytes” or “non-useful bytes” strikes me as similar to the claims of “junk DNA”. They’re not dark or non-useful.
Let's forget about "non-useful", this was a mistake and will be corrected. The word 'dark' is still relevant however. The adequate comparison is not "junk DNA", but instead "dark silicon":
https://ieeexplore.ieee.org/abstract/document/6307773
We're talking about a general % of executable size that's necessary for a smaller % of use cases in program function.
I'm all for trade-offs, but IMHO they should be transparent.
The title of the post is "Go Executable Files Are Still Getting Larger". Upon further reading and conversation here it seems this is possibly not true, nor what the post is about. If we believe Russ's comments, Go executable sizes haven't increased much in general. Perhaps the reason you're seeing increases in Cockroach DB is because you keep writing more code for Cockroach DB?
Now the point has shifted to this notion of "dark bytes". So the article is about ... how the way you previously diagnosed the contents of binaries doesn't work anymore? That's fine and legitimate, but it seems like the point is over-extrapolated to become a criticism of the Go team.
Russ's example was just the "gofmt" program.
> Perhaps the reason you're seeing increases in Cockroach DB is because you keep writing more code for Cockroach DB?
If that was the only reason, then the % overhead would remain constant-ish. But it is increasing. So there is a non-linear factor for _some_ go programs (like cockroachdb) and it's still unclear what that factor is.
If there is superlinear growth in binary sizes as the project grows – for example, if some part is O(n^2) in the number of interfaces – then that's certainly interesting. If you demonstrated that such superlinear growth is happening, and wrote an article based on that, people wouldn't be so critical.
If Go binaries are getting bigger because Go produces bigger binaries for the same source code over time, then that's also interesting. If you demonstrated that Go binaries are getting more and more bloated over time for the same source code, and wrote an article based on that, people wouldn't be critical.
But as it is, you kind of just complained that CockroachDB is getting bigger, tried to blame it partly on the Go compiler producing more bloated code over time, partly on a mystical "dark area" which you don't understand, you mentioned superlinear growth only in the comment section, and you didn't actually gather data or do experiments to prove or disprove any of the things you're claiming as a cause. That's why people are complaining.
Where? The argument is _precisely_ that the growth is occurring in non-code areas.
> partly on a mystical "dark area" which you don't understand
The _observation_ is that the growth is happening in an area of the file that's not accounted for in the symtable. That's what makes it "dark". It's not mythical: it's _there_ and you can observe it just as well as anyone else.
> you mentioned superlinear growth only in the comment section
it's in the reported measurements.
> and you didn't actually gather data or do experiments to prove or disprove any of the things you're claiming as a cause
The analysis is stating observations and reporting that the size is increasingly due to non-accounted data. That observation is substantiated by measurements. There's no claim of cause in the text!
But how is this important? If the thing you're optimizing for is "total Go binary size", then all that matters is the total size of binary! How bytes are organized internally is irrelevant to this metric.
You should redo the analysis where you compile an old version of Cockroach DB (say v1.0.0) with Go versions 1.8 through 1.16, and then see what the numbers say. Your current analysis, which doesn't account for growth in the code base at all, or tries to account for it by deep-diving into the internal organization of the binary, is not sound.
Not quite so if the task is to work on reducing the metric.
When the size is attributed to data/code that's linked to the source code, then we know how to reduce the final file size (by removing data/code from the source code, or reducing them).
When the size is non-attributed and/or non-explained (“dark”) we are lacking a control to make the size smaller over time.
The Go source code is available to you. Russ has pointed out there’s no existing tool to break down those “dark” bytes but that they do serve a purpose, but perhaps you could work on that tool instead of complaining that it’s not covered by the symbol table.
I'm not going to respond point by point because those points are kind of moot if my accusations were based on an incorrect reading.
Everything has trade offs. Go is not the easiest language in which to write highly efficient code. Cockroach generates some code to help here. Certainly at this point there’s pain around tracking memory usage so as to not OOM and there’s pain around just controlling scheduling priorities. But then again, had it been C++ or Rust perhaps getting to table stakes correctness would have taken so long it wouldn’t have mattered.
Some cost just comes from running distributed replication and concurrency control. That’s unavoidable. Some also comes from lack of optimization. Postgres has been around and has some very optimized things in its execution engineer.
Also, if you run Postgres in SERIALIZABLE, it actually does quite badly, largely because that isolation level was bolted on and the concurrency control isn’t optimized for it. Crdb was core-for-core competitive in serializable on some workloads last time I checked.
In the same way, the functab data in Go is not used all the time either, only when generating stack traces.
Also since that original article from 2011 was published, the phrase "dark silicon" was extended to designate silicon IP which is not directly necessary for a given target application but is embedded for the occasional use by a niche in the same market.
In the same way, all languages (not just Go) embed constructs in generated code that are there only to handle edge cases in certain applications/deployments, and are inactive for 90%+ of executions.
Might it be possible to stream binaries or to detect junks which could be unloaded like an json parser which is only needed when reading json
Because even without a swap partition/file, the whole executable will not block physical memory, but will page in/out as needed. And whole sections of it will never be loaded at all.
Since the executable is mapped read-only, the pages loaded in physical memory can also be shared between multiple instances of the process.
The DWARF data is currently so represented, and so was pclntab prior to 1.16.
Today, the DWARF data is still present; the symbol for pclntab has an advertized size of zero, and the amount of data not represented in the symbol table and ELF section headers has grown.
> If the 73% of the binary diagnosed as “not useful” were really not useful, a reasonable demonstration would be to delete it from the binary and see the binary still run. It clearly would not.
Probably not if all of it was removed at once.
It could be that just 5% of it is useful and removing all of it would produce a non-working binary. What does the experiment prove exactly?
Look you can claim that "having the necessary metadata for garbage collection and reflection in a statically-compiled language takes up a significant amount of space" but without clear evidence of how much space that is, with proper accounting of byte usage, this claim is non-falsifiable and thus of doubtful value.
The article made the claim that 70% of space is wasted "dark bytes". The article should prove the claim, which it did not. It's an extraordinary claim that really requires more evidence than just an off-hand napkin calculation and talk about mysterious "dark bytes".
It takes very little time to write up something that's wrong.
It takes much more time to write a detailed rebuttal.
What you're doing here is pretty much the same trick quacks, young-earth creationists, and purveyors of all sorts of pseudo-scientific claims pull whenever they're challenged. Any fool can claim the earth is 6,000 years old. Proving that it's actually several billions years old requires deep insight in multiple branches of science. People stopped doing this after a while as it's so much effort and pointless as they're not listening anyway, so now they pull the "aha, you didn't falsify my claim about this or that bullshit I pulled out of my ass therefore I am right" zinger and think they look Very Smart And Scientific™.
But that's not how it works.
Also just outright disbelieving people like this is rather rude. You're coming off really badly here and your comment has the strong implication that Russ is outright lying. Yikes!
This is incorrect. The claim is that the bytes are either non-accounted, or motivated by technical choices specific to Go.
> What you're doing here is pretty much the same trick quacks [...]
Look the article has some measurements with numbers which you can readily reproduce on your own computer, and the methodology is even described. The main claim is that "it's unclear what these bytes are about". The previous claim that they were "non-useful" was retracted. The data is there, and there's a question: "What is this data about?"
The text is even doubling down by spelling out "there's no satisfying explanation yet".
> outright disbelieving people like this is rather rude
We're not in the business of "believing" or "disbelieving" here I think? There's data, there's measurements, and there are explanations.
After my comments and that of others, Russ provided a more elaborate, more detailed (and at last, falsifiable in the positive, epistemological sense of the word) explanation deeper in the thread. Now we can make the work of looking into it and check the explanation.
> your comment has the strong implication that Russ is outright lying
Your understanding is flawed then? There was no assumption of lies implied.
That's not what it says; with "70% of a couple hundred megabytes are copied around for no good reason" written in bold no less:
> That’s right! More than two thirds of the file on disk is taken by… bits of dubious value to the software product. > > Moreover, consider that these executable files fly around as container images, and/or are copied between VMs in the cloud, thousands of times per day! Every time, 70% of a couple hundred megabytes are copied around for no good reason and someone needs to pay ingress/egress networking costs for these file copies. That is quite some money being burned for no good reason!
That claim was retracted a while ago already on the original version; the syndicated copy on the crl web site will be updated at some point.
This is also a trick peddlers of pseudoscience pull by the way. Honestly, you're coming off even worse now and this is reflecting pretty badly on all of CockroachDB to be honest. I don't know what your relationship with CockroachDB is exactly (if any), but it's on their website, and it's not a good look. If I was a manager there then I'd back-pedal, unpublish the entire thing, and issue an apology.
The article linked in this thread is a syndicated copy of an original article published elsewhere, as clearly stated by the attribution section at the bottom. It's reasonable to expect that changes to the original will only be updated in the copy with a delay.
But whatever, this is pointless. Russ was right and it's hard to take any of this in good faith. It feels like you're going to great lengths to avoid saying "oops, I was wrong".
I wrote this because there was no mention of "waste" anywhere in OP.
I respectfully disagree. I believe there is value in pointing out the false claims in a long blog post even when there isn't time to write a full-length rebuttal.
Oh, you don't want to do that? That's not a surprise. Neither do I. Definitely not on my agenda today.
But I'm not making wild accusations. If you're going to, you probably shouldn't be surprised when we're not exactly impressed.
The compiler is all open, and as such things go, fairly easy to read. "As such things go" is definitely doing some heavy lifting there, but, still, for a compiler of a major language, it's a relatively easy read.
The vague intimation that there's something hidden and sneaky going on is hard to give much credence to.
It's an ELF binary; all that's relevant are the program/segment headers and dynamic table. The section headers and non-dynamic symbol table are just there for orthogonality and to make the debugger's life a little easier (and the debugger would much prefer DWARF data and doesn't care about the section headers, tbh)
- The expansion of pclntab in Go 1.2 dramatically improved startup time and reduced memory footprint, by letting the OS demand-page this critical table that is used any time a stack must be walked (in particular, during garbage collection). See https://golang.org/s/go12symtab for details.
- We (the Go team) did not “recompress” pclntab in Go 1.15. We did not remove pclntab in Go 1.16. Nor do we have plans to do either. Consequently, we never claimed “pclntab has been reduced to zero”, which is presented in the article as if a direct quote.
- If the 73% of the binary diagnosed as “not useful” were really not useful, a reasonable demonstration would be to delete it from the binary and see the binary still run. It clearly would not.
- The big table seems to claim that a 40 MB Go 1.8 binary has grown to a 289 MB Go 1.16 binary. That’s certainly not the case. More is changing from line to line in that table than the Go version.
Overall, the claim of “dark bytes” or “non-useful bytes” strikes me as similar to the claims of “junk DNA”. They’re not dark or non-useful. It turns out that having the necessary metadata for garbage collection and reflection in a statically-compiled language takes up a significant amount of space, which we’ve worked over time at reducing. But the dynamic possibilities in reflection and interface assertions mean that fewer bytes can be dropped than you’d hope. We track binary size work in https://golang.org/issue/6853.
An unfortunate article.