https://github.com/chrisstroemel/Simple/blob/master/cma-comp...
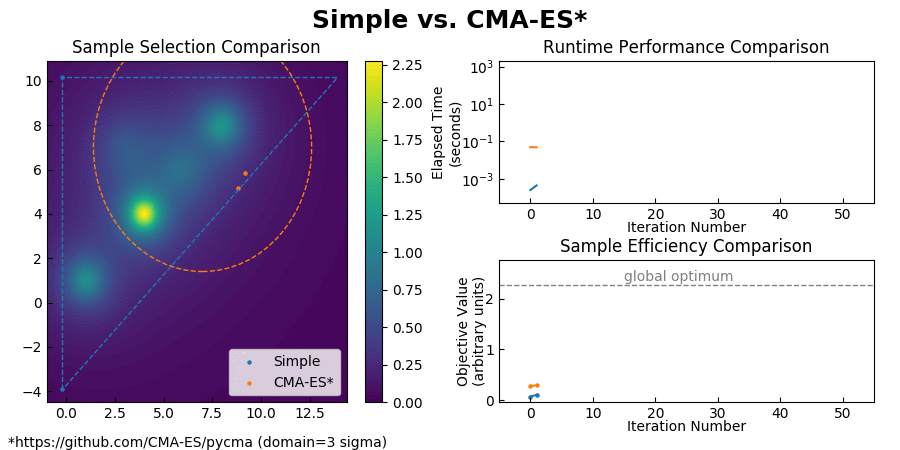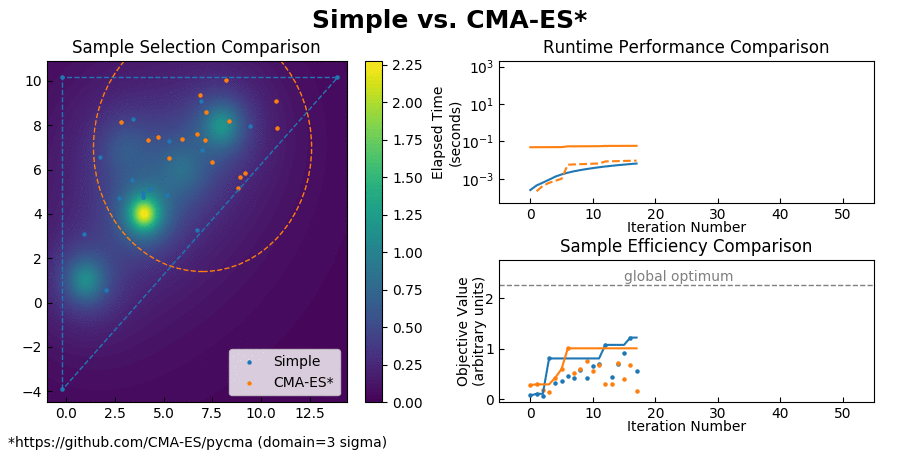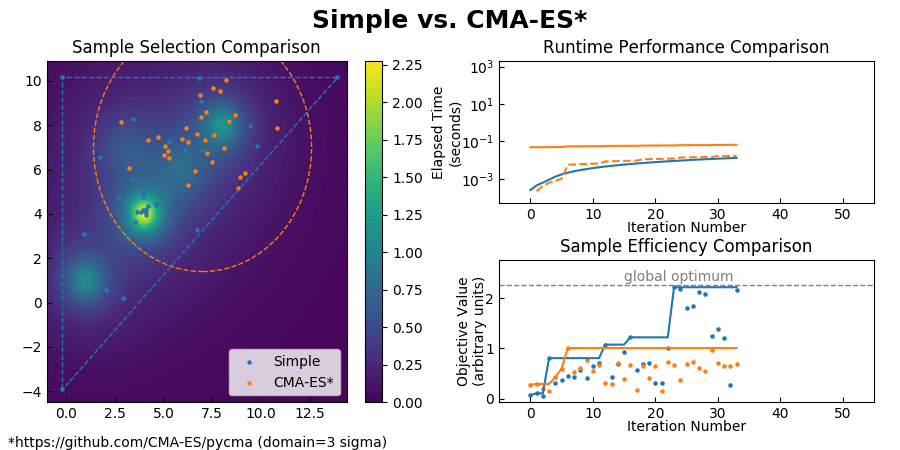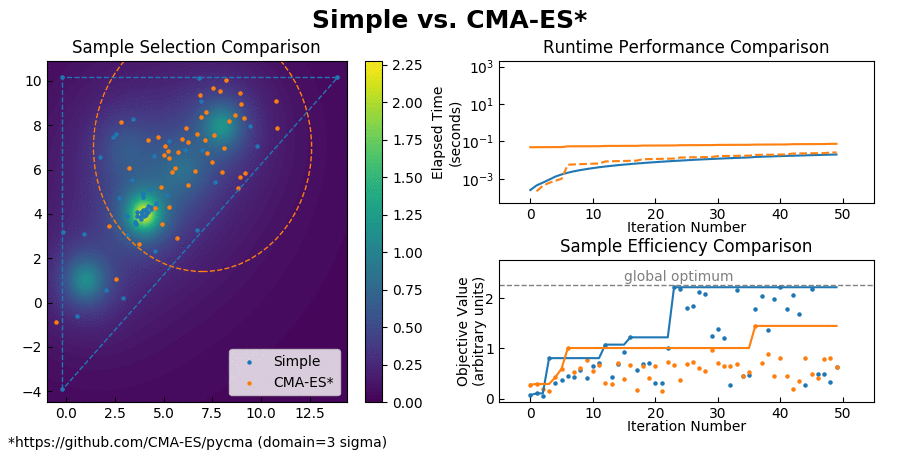
Simple is a constrained optimizer while CMA-ES is unconstrained, so I ended up choosing a sigma value such that the three sigma cutoff could be considered its faux "optimization domain." I gave the two algorithms equal areas to operate on, however CMA-ES is very sensitive to where it's initialized at. If I had started it near the global optimum it would have instantly converged without performing any optimization at all, so then there was also the issue of deciding on a "fair" starting location. Trying to get around this, I briefly tried the comparison on the Griewank function from -5:5, however CMA-ES showed nonconvergent behavior.
CMA-ES seemed to have a higher startup cost than Simple, but very similar per-iteration runtime performance. Sample efficiency ranged from totally nonconvergent to instant convergence without global search, depending on where it was started.
If you have any suggestions for a better testing methodology I would really appreciate them, because I'm still not quite satisfied with this comparison.
When I need constraints on CMA-ES for real world stuff I've been using a simple equation to map the output of the parameters before using them:
y = a + (b - a)*(1 - cos(pi * x / 10)) / 2
If I get a chance today I'll try and run your code and play around a bit. Really cool stuff!
I'm currently away from my computer but I can produce a comparison animation in a few hours. While I am biased, I strongly suspect that Simple will have superior sample efficiency and at least similar performance.