News for hackers. Stuff that matters.
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by bra-ket on Friday January 05, 2018 @09:39PM (#16083535)
it's really a pity that after 75 years of AI research the best thing we've got is still based on gradient descent, a brute force trial and error.
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by log_base_login on Friday January 05, 2018 @09:58PM (#16083598)
As much of a pity that, 70 years later, we are still using transistor based computers originally derived from three wires stuck in a piece of rock[1] by some very innovative fellows at Bell Labs[2]?

[1]http://images.computerhistory.org/revonline/images/500004836... [2]http://www.computerhistory.org/revolution/digital-logic/12/2...
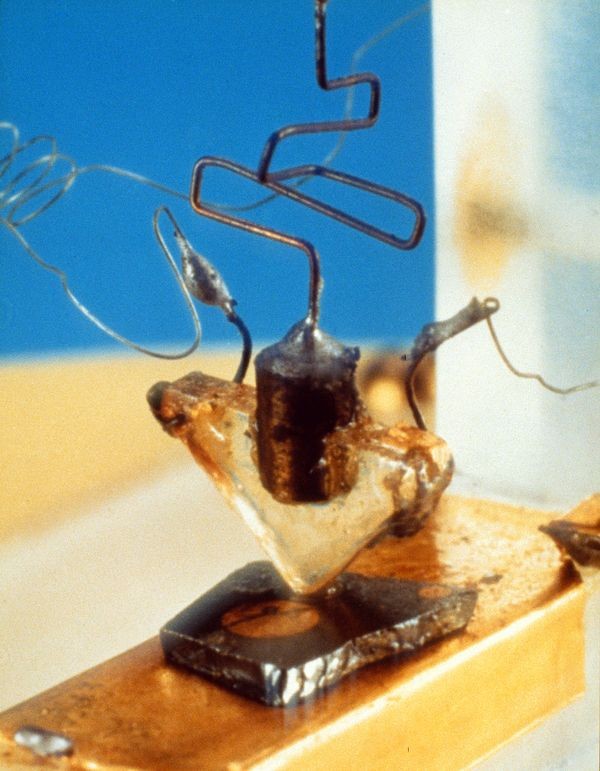
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by nostrademons on Saturday January 06, 2018 @12:45AM (#16084043)
As much of a pity as that after 3 billion years, all life is still based upon selection bias and random genetic mutations, a brute force trial and error?
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by Cybiote on Saturday January 06, 2018 @03:46AM (#16084438)
This is a poor example considering evolution is anything but brute force trial and error. Each organism can be considered either an hypothesis or a collection of hypotheses about the background environment (https://arxiv.org/pdf/0911.1763v3.pdf, https://aeon.co/essays/consciousness-is-not-a-thing-but-a-pr...).

The algorithms which allow AlphaGo or the Libratus Poker AIs to achieve superhuman play have a direct correspondence with natural selection (and learning rate with selection strength). There is idea sharing between evolutionary game theory and learning, up to algorithms to play extensive form games with imperfect information such as this, based on replicator dynamics: http://dl.acm.org/citation.cfm?id=2617448

Evolution, per genome trajectory, also improves in its ability to evolve, as seen in evolvability.

Returning to the grandparent's original lament on stochastic gradient descent, I do agree with them. I suspect the need for better has not been seen due to non-supervised and incremental learning remaining minor areas of study. Artificial separation between learning and prediction allows "hacks" like batch-norm to somewhat suffice. It does seem unlikely that we will never need to take into account curvature of information manifolds while learning. Note that evolution uses curvature too.

Anything order than SGD has proven expensive but there are promising approximations, as found in KFAC or Projected Natural Gradient Descent, allowing me to close this post with yet another link between learning and evolution.

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by mturmon on Friday January 05, 2018 @11:39PM (#16083883)
Following a gradient is smarter than trial and error. You can make an argument that, in high-dimensional parameter spaces, it’s hard to do better (because, gradient descent is linear in the number of dimensions).

Ordinary Metropolis-Hastings, for example, is closer to trial and error.

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by tmyklebu on Saturday January 06, 2018 @10:53AM (#16085741)
> You can make an argument that, in high-dimensional parameter spaces, it’s hard to do better (because, gradient descent is linear in the number of dimensions).

Nitpick: If you're interested in solving optimisation problems, it's very easy to do better than gradient descent. Gradient descent performs very poorly when the directional curvature of the objective function varies too much with the direction. Newton's method, quasi-Newton methods, and nonlinear conjugate gradient are some of the more ingenious, beautiful, and clean ways; there are also some dirty, hacky ways to go.

It is a little bit interesting that fancier optimisation algorithms than gradient descent are unnecessary or unhelpful in some large-scale applications.

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by mturmon on Saturday January 06, 2018 @01:25PM (#16086663)
You mention Newton’s method, but of course that requires second order information which, as I mentioned, is not generally workable in high dimensions. You have to be careful with quasi-Newton methods like conjugate gradient for the same reason.
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by tmyklebu on Saturday January 06, 2018 @01:45PM (#16086764)
> You mention Newton’s method, but of course that requires second order information which, as I mentioned, is not generally workable in high dimensions.

Why would you say that second-order information is "not generally workable in high dimensions"? We regularly run Newton's method on problems with tens of millions of variables today.

And Newton's method isn't the only way to use second-order information. It is easy to access, for example, Hessian-times-vector information using the same reverse-mode differentiation that's so popular today, using only a constant factor more time.

> You have to be careful with quasi-Newton methods like conjugate gradient for the same reason.

What reason, exactly, is that?

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by mturmon on Sunday January 07, 2018 @01:21AM (#16089566)
I meant, in general settings (ie, no special problem structure), that you need full Hessians for Newton’s method. And, regarding conjugate gradient, in (non-DL) settings that I’m used to, that for good results you need preconditioners which are also second order.

Could you provide a reference to a 10^7 size problem that is being optimized with Newton’s method? I’d be indebted.

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by tmyklebu on Sunday January 07, 2018 @02:38AM (#16089791)
> I meant, in general settings (ie, no special problem structure), that you need full Hessians for Newton’s method. And, regarding conjugate gradient, in (non-DL) settings that I’m used to, that for good results you need preconditioners which are also second order.

Yep, but often sparsity is present or the objective function is reasonably well-behaved. The former can save straight Newton; the latter will make nonlinear CG or quasi-Newton methods converge rapidly. (Quasi-Newton methods build a simple model of the Hessian from gradient and step information, usually using repeated low-rank modifications of a diagonal matrix. There are variants, like L-BFGS, that have an explicit, tunable limit on the number of additional vectors to be stored. This work really well for some reason---usually far better than gradient descent, and almost never more than a small constant factor slower)

> Could you provide a reference to a 10^7 size problem that is being optimized with Newton’s method? I’d be indebted.

Interior-point methods for linear programming form the Hessian of a barrier function at each iteration, then (sparse) Cholesky factorise it, then do a few backsolves to find a search direction. (Special hacks generally go into these "few backsolves" to speed convergence.) This is a damped Newton method. Commercial implementations include CPLEX, Gurobi, and MOSEK; there are a great many less-commercial implementations as well.

Chih-Jen Lin's LIBLINEAR uses a truncated Newton method (solve Hessian*direction=gradient by linear conjugate gradient, stopping early when sufficient accuracy has been obtained to take a step) to create linear classifiers for data.

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by tomrod on Saturday January 06, 2018 @12:32AM (#16084011)
> because, gradient descent is linear in the number of dimensions

Yes, but increasing dimensions does not mean the manifold of the problem space increases the same.

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by jclos on Saturday January 06, 2018 @05:56AM (#16084742)
Its simplicity is its power. More complex methods (e.g. second order methods) tend to get attracted to saddle points and produce bad results. Some metaheuristics like evolution strategies are also used in some specific cases (reinforcement learning). Minibatch gradient descent + reasonable minibatch size + some form of momentum is the best we have.
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by electricslpnsld on Saturday January 06, 2018 @01:12AM (#16084110)
If you can’t reasonably get at or use second order information, how else are you going to optimize arbitrary objectives?

Well, come to think of it it, why don’t DL approaches use BFGS instead of gradient descent?

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by fwilliams on Saturday January 06, 2018 @01:39AM (#16084164)
There is literature on Quasi-Newton and Krylov Subspace methods for training Neural Networks. For example, https://dl.acm.org/citation.cfm?id=3104516.

I think the primary reason that such methods are not used much in practice is memory and computational cost: each function evaluation is expensive and you need to solve a very large system at every iteration.

Also to reply to a sibling comment, you can add momentum and step length adjustments to second-order methods in much the same way as in steepest-descent to help escape saddles. The only difference is how the descent direction is chosen for the optimization.

Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by steev on Saturday January 06, 2018 @08:15AM (#16085128)
This is correct - second order methods are great in theory, but they are generally computationally prohibitive for high dimensional problems.
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by jph00 on Saturday January 06, 2018 @01:18AM (#16084121)
Second order methods are attracted to saddle points in high dimensional spaces. The math and practice of optimizing these surfaces has a lot of nuances like this so much of the stuff you learn in your convex optimization class doesn't apply too well.
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by steev on Saturday January 06, 2018 @08:23AM (#16085145)
Do you have any recommendations on sources to read about this? Everything I've read discusses the use of the Hessian to not only determine you are at a saddle point but to also use its eigenvalues to escape.
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by plafl on Saturday January 06, 2018 @02:15AM (#16084258)
I have not used it but there is an implementation in PyTorch: http://pytorch.org/docs/master/optim.html#torch.optim.LBFGS
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by bra-ket on Monday January 08, 2018 @07:23PM (#16102326)
the question is - why do you need to optimize in the first place? why don't you look up an answer instead of solving a mathematical optimization problem?
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by pacavaca on Friday January 05, 2018 @10:48PM (#16083735)
Assuming that AI tries to mimic the way humans learn and evolve, those methods haven't changed for hundreds of thousands of years and brute-force trial and error is just one of them. It's kind of fundamental...
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by comstock on Friday January 05, 2018 @11:43PM (#16083896)
It doesn’t really try to mimic the way humans learn and evolve...
Re:“Deep Learning has outlived its usefulness as a buzz-phrase” by maxtollenar on Friday January 05, 2018 @11:22PM (#16083839)
Mostly because the loss function space is not well understood, we need to do some kind of descent