If I recompile blake2sp with "/O2" optimization, it improves to 171MB/sec. I ran tests with "/Od" optimizations disabled because the default Crypto++ library project has optimizations disabled when it makes the lib file. Therefore, every hash had no optimizations to keep the comparisons apples to apples.
I see your Javascript code of BLAKE2 on github so I'll try it and compare. (https://github.com/dchest/blake2s-js)
>Also, there is no reason to use such large buffer sizes, I suspect this only makes benchmarks more unreliable.
I chose 500MB because I wanted the fastest hashes (CRC32, MD5) to take at least 1 second and many data sizes I want to hash will be 10GB+.
Too slow! You're doing something wrong or measuring some slow implementation :) It should be more than 500 MB/s.
Therefore, every hash had no optimizations to keep the comparisons apples to apples.
That's not apples to apples at all. Most performant code is written specifically to be optimized by compiler. Use /O3 for benchmarking. Also, you just wrote that you were measuring a hand-optimized assembly version and then compared it to a C version compiled with optimization disabled? O_o
I chose 500MB because I wanted the fastest hashes (CRC32, MD5) to take at least 1 second and many data sizes I want to hash will be 10GB+.
Then call the update function with a reasonable 8K buffer many times. Using such large buffers will generate a lot of noise in benchmarks.
* * *
Speaking of JS, you can try my newer implementations/ports by cloning https://github.com/StableLib/stablelib. run ./scripts/build, cd into packages/blake2s (/sha3, /sha256, etc.) and run: node lib/.bench.js Note that SHA-3 (and SHA-512, BLAKE2b [not implemented yet]) is slow in JS compared to SHA-256, BLAKE2s, etc. because it uses 64-bit numbers, so in JS I have to emulate them by using two 32-bit ones for low and high bits.
* *
Benchmarks on Intel Skylake:
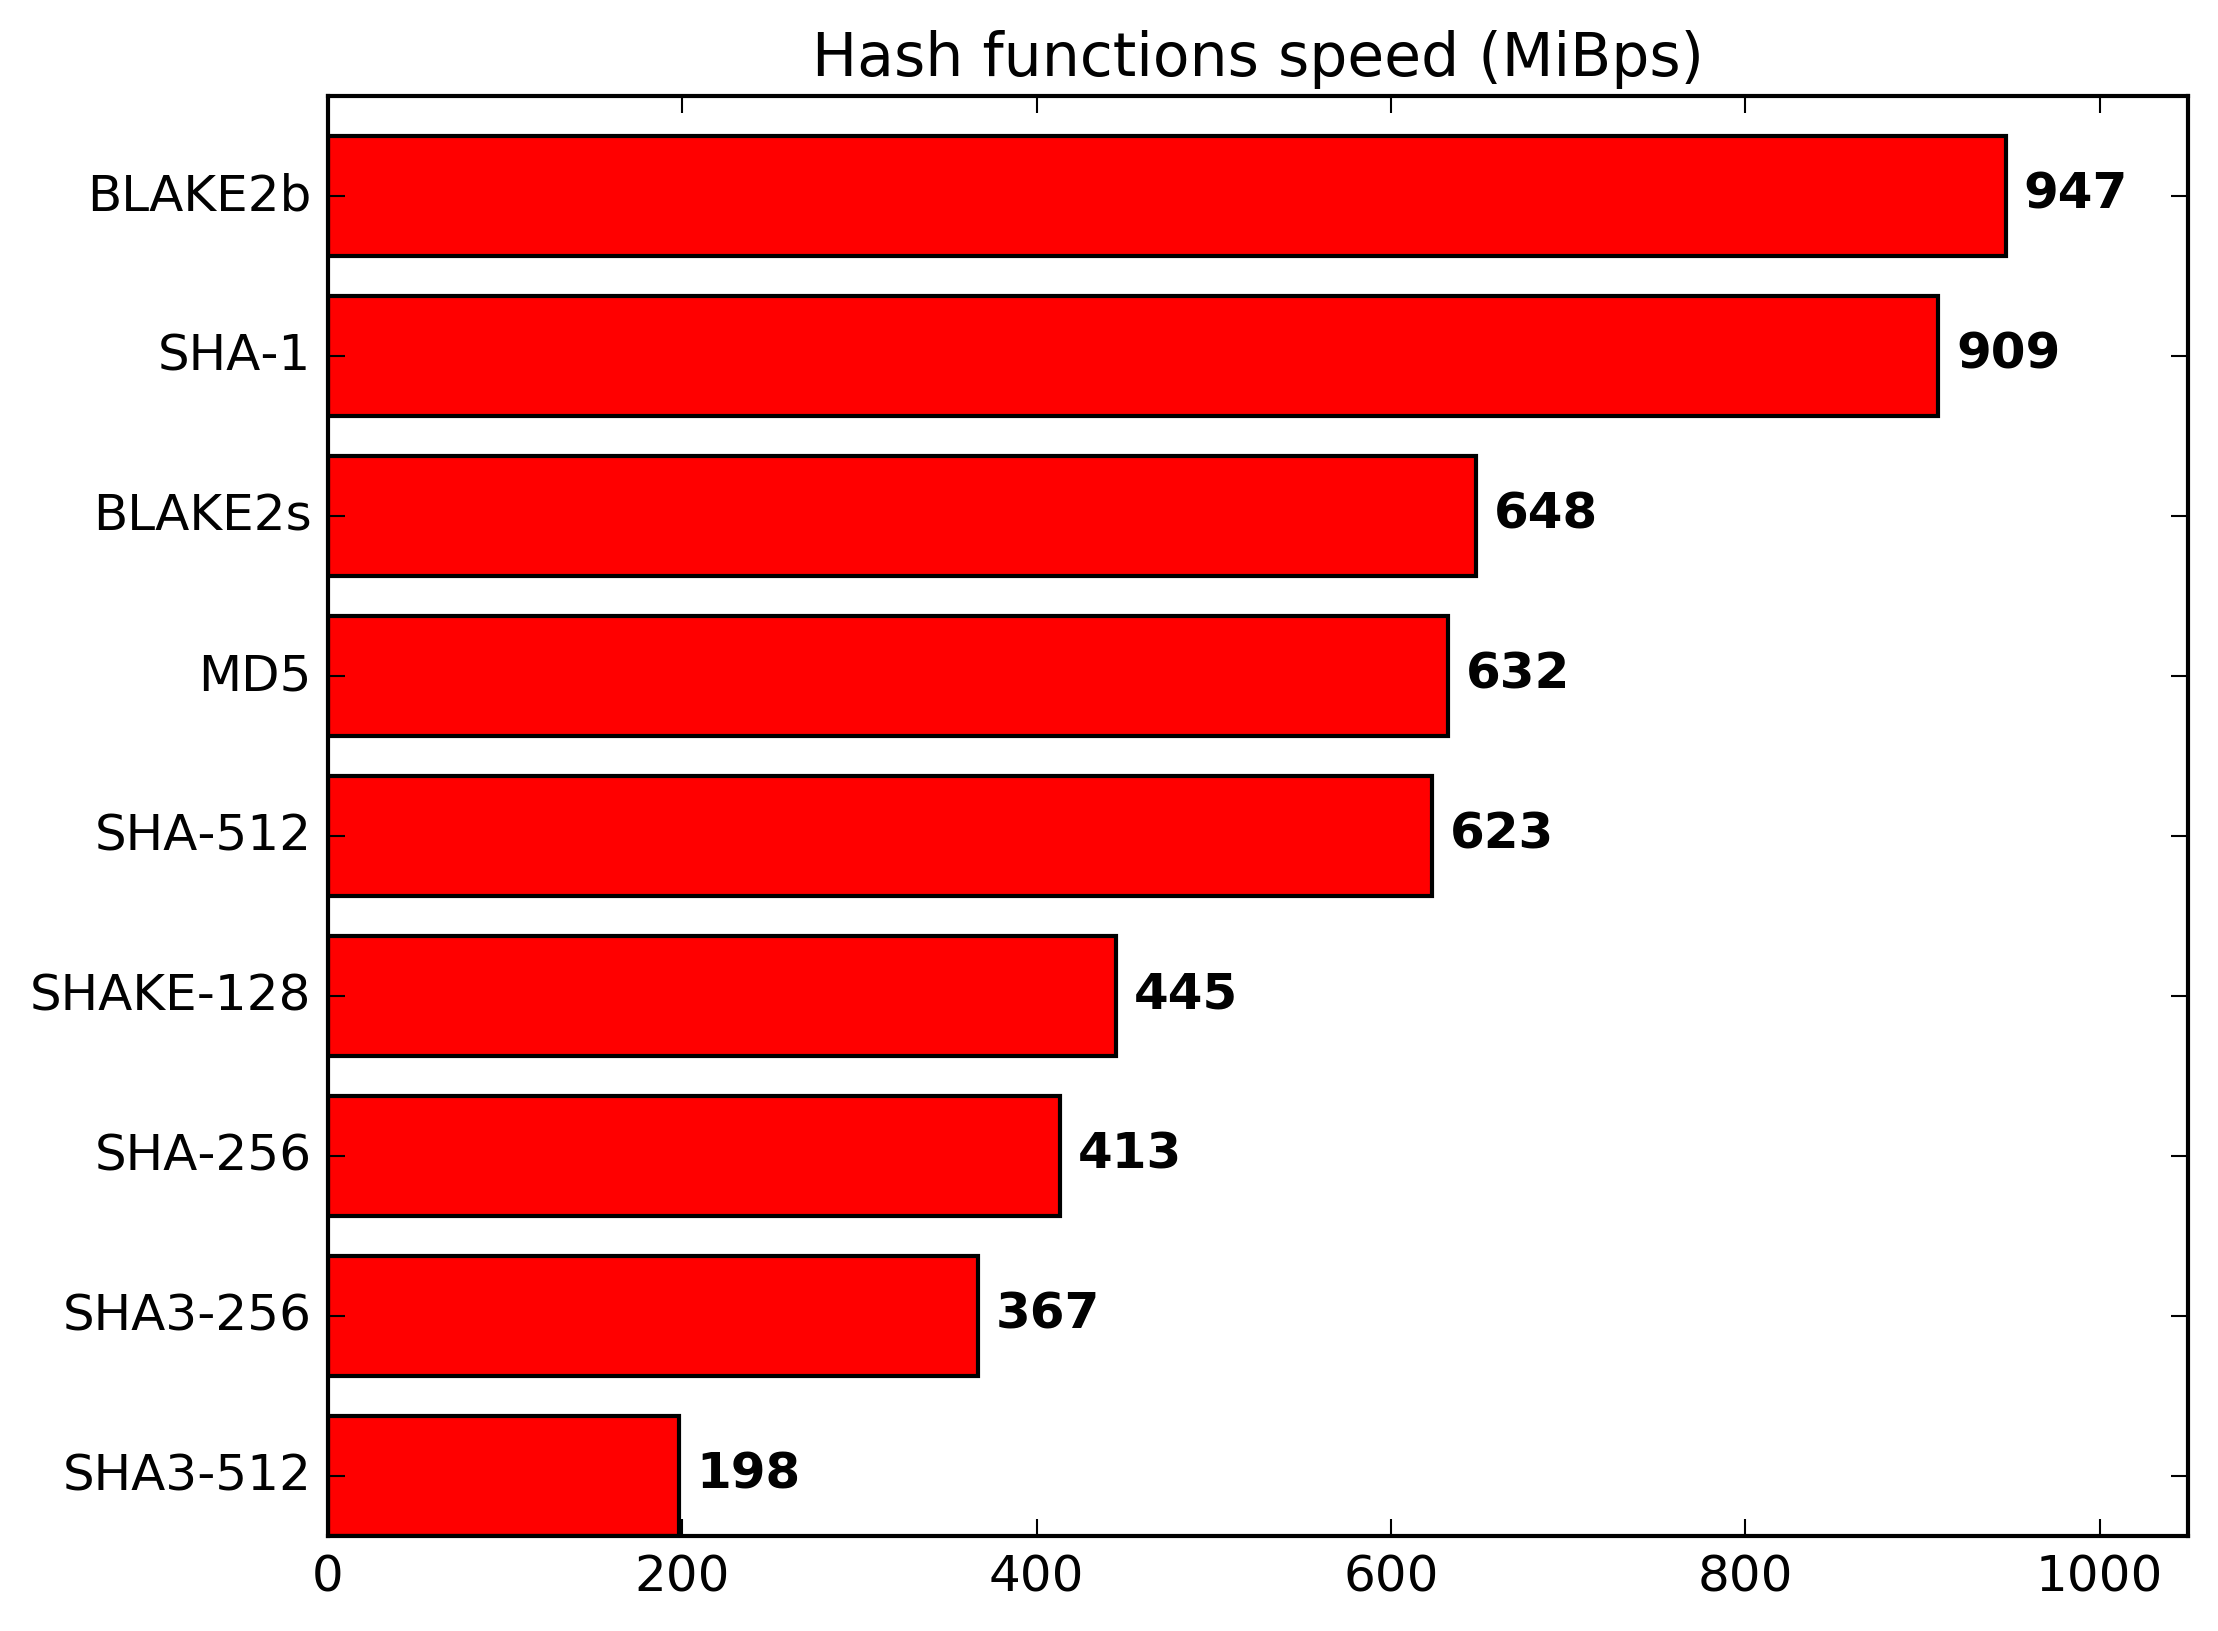
I do now notice that my ASUS motherboard monitor software is reporting that my CPU is at 1.2GHz instead of 3.3GHz. There's probably something wrong there. However, even if I get it up to 3.3GHz, the relative speeds between different benchmarks won't change. I got the same relative numbers on the Macbook.
>measuring a hand-optimized assembly version and then compared it to a C version compiled with optimization disabled? O_o
Because there's lots of Wei Dai code that's C++ code instead of asm. He delivered his MSVC project with optimizations disabled instead of "/O3" so it made the most sense to start with optimizations disabled everywhere as a preliminary benchmark. If I recompile Wei Dai's code with optimization, it will make Crypto++ perform faster and make blake2sp look slower. In the end, it's a moot point because blake2sp with "/O2" is still slower than Crypto++ SHA256.
>Using such large buffers will generate a lot of noise in benchmarks.
Why? If you study the blake2sp source code, you'll see a loop inside the hash update() function to handle arbitrary sizees of buffers. Why does a loop outside that update() mean "less noise"? Why does adding more function calls of BUFSIZETOTAL divided by 8192 equal less noise?
Just do it. If it's slower, you're doing something wrong. Which implementation of blake2sp are you measuring? It should be at least 1.5x as fast.
Why? If you study the source code, you'll see a loop inside the hash update() function. Why does a loop outside that update() mean "less noise"? Why does adding more function calls of BUFSIZETOTAL divided by BLOCK PROCESSING SIZE equal less noise?
Because you'll be measuring a lot of memory copying time apart from hashing time. Dealing with memory outside of CPU cache introduces a lot of variance.
I suggest that instead of our discussion you should try to reproduce the results of https://bench.cr.yp.to (which is a highly trusted source, e.g. it was used during SHA-3 competition by NIST and participants): if something doesn't approximately match it means you did something wrong. In the process, you'll learn how to properly benchmark hash functions and make some sciency science by reproducing results! :-)
However, for relative MB/sec performance comparison to SHA256, it seems to point back to the blake2 official reference code (non SSE) being very slow. Wei Dai Crypto++ also happens to have BLAKE2 algorithm and when I executed that, it ran at 525MB/sec which was faster than SHA256 and also faster than SHA1. No outer 8k chunk loop necessary for Crypto++ benchmark.
>Because you'll be measuring a lot of memory copying time apart from hashing time.
Yes, I notice the numerous memcpy() functions in the blake2s?-ref.c. For additional tests, I rewrote the loop to call update() on chunks and tried various sizes (8k, 16k, 32k, ... 256k, 512k, 1MB). At 256k chunks and below, I got 235MB/sec which was an improvement but still slower than SHA256. As stated above, the real key was to use an optimized BLAKE2 algorithm instead of the official reference code.
>you should try to reproduce the results of https://bench.cr.yp.to
I can't tell if the blake2 entries in https://bench.cr.yp.to are using official reference or optimized code so trying to replicate those results with official reference files may be a wild goose chase.
https://bench.cr.yp.to/impl-hash/blake2s.html
Code mirror: https://github.com/floodyberry/supercop
Yeah, of course reference implementation is a lot slower — it's for algorithm reference, so has readable code, which is slow. It can even be greatly improved by just unrolling loops and inlining message indexing by sigma constants, even without SSE (like my JavaScript implementation).
As for memory copying — I didn't mean memcpy(), what I meant is that your CPU would have to get chunks of your huge buffer from RAM, which is slower and has more unpredictable performance.
Exactly! That's why my original post had the footnote that I using the slower blake2sp reference code. Same situation as the SHA-3 reference code being the slowest implementation.
>As for memory copying — I didn't mean memcpy(), what I meant is that your CPU would have to get chunks of your huge buffer from RAM, which is slower and has more unpredictable performance.
But this observation also applies to all the other hash performance tests. If the blake2sp hash is handicapped by computing large RAM buffers beyond the L1/L2/L3 caches, the MD5/SHA1/SHA256/etc are also handicapped the same way. Whatever "noise" exists in the tests can be evened out by multiple executions.
Restricting the tests to tiny memory sizes that fit in L1/L2/L3 is not realistic for my purposes.
For real numbers on many platforms, see https://bench.cr.yp.to/results-hash.html (warning: very large page)
For long messages on 2015 Intel Core i5-6600; 4 x 3310MHz:
This means BLAKE2s is close to 700 MB/s, and BLAKE2sp will hash data at more than 1 GB/s.Here are the SHA-256 implementations measured: https://bench.cr.yp.to/impl-hash/sha256.html
As you can see, the winner varies by platform, but in most cases OpenSSL wins, and Wei Dai's implementation is close.