Unless you have some sort of replication or consensus, this is still just best-effort delivery. For example, the message could be acknowledged & fsynced followed by drive death. At scale, this would happen.
However, with asynchronous best-effort replication, broker death would be much less likely to lead to a loss of messages.
In general, it's all about playing the odds. Acknowledged writes can still be lost in the best of systems if the entire DC catches fire.
If you tune Kafka settings, you essentially get this behavior. You have to ensure ZK is up, but it will allow all topics to be published to so long as a single broker is alive.
The closest I can get is allowing sloppy leader election, but that will definitely, definitely lose writes that have been ACK'd by a stale leader who comes back and has to become a follower. So I can get Kafka to basically accept all writes regardless of level of cluster degradation, but I can't keep it from dropping some of those writes silently onto the floor.
Did you test this or is it just a general view? What sort of write rate are you looking for, per topic?
I care that as long as even one node in the system is alive, it will accept writes, and those writes will eventually propagate and converge on the union set of all writes ever observed, without obliterating any ACK'd observed writes, as the system as a whole moves toward a less degraded state.
I'd want topics themselves to be able to be basically "free" to create, and the write latency to remain stable over arbitrarily large datasets. Write rate isn't really much of a consideration since it's almost embarrassingly low (hundreds per second).
Fair nuff, I asked because I was curious if you were assuming that eventual consistency was necessary for high availability.
> Write rate isn't really much of a consideration since it's almost embarrassingly low (hundreds per second).
Yup, looks like my concern above is the case. A single consensus replica set will do that no problem. I'd use raft if you're in a single geo location or epaxos otherwise (the epaxos source is a little early and needs eyeballs/production diversity testing, but the algorithm is absolutely solid). There's no reason to borrow all the troubles of CRDT's when it's not needed.
Edit:
Example from the epaxos paper, this is latency vs throughput for 3 replicas in one geo location: http://charap.co/wp-content/uploads/2015/10/latency_over_thr...
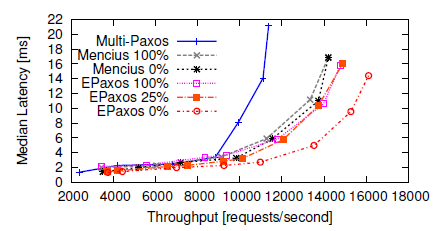
You seem extremely concerned about a fault tolerant system experiencing more faults than the majority, which I think is quite easily dealt with, and utterly blithe about making inconsistency your best case.
At this kind of request rate I'd honestly just shove things in postgres and call it good. There's just no reason to build out a bunch of CRDT complexity when you don't _need_ it.
Does that give you a better perspective for my availability concerns?
I also don't have "on demand" infrastructure. I have to deploy to a fixed footprint of bare metal hardware.
I'm "utterly blithe" about inconsistency being my best case for a variety of reasons:
1) I know my use case extremely well.
2) I know that within that use case there are several places where availability is the #1, #2, and #3 priority because the system being unavailable for any time at all has a non-trivial direct financial impact.
3) I know within that use case where there are necessary points of consistency and how to move them out of the critical path that requires extreme availability.
4) I know exactly the problem that CRDTs solve for me, and exactly why I need them in this case, and how to avoid them with simpler immutable/idempotent write patterns where possible.
5) I have to be able to tolerate very high proportion of the infrastructure experiencing temporary and/or permanent failure because the places I have to deploy into are no where near the level of reliability of even a low-mid tier data center in the US. Janky telcos, natural disasters, malicious operators, and flimsy power delivery are the norm.
Edit: I see you edited in a longer comment after my question above. I was just curious, not looking to pick a fight. Suffice it to say we have very different perspectives on how to attack those requirements. I'm bowing out now, cheers!.
1) Anything that is suggested which avoids data loss via consistency models is going to reduce my availability to unacceptable levels.
2) Anything that is suggested which keeps my availability up where it needs to be and doesn't use CRDTs, and/or a sufficiently similar semantic guarantee, is going to silently lose data due to "lost-updates" (ACK'd writes that get obliterated during conflict merges and are now gone forever).
At a minimum I need sibling behavior for conflicting writes to ensure that some half-baked LWW strategy that's barely better than "pick at random" doesn't kill my data (which has very high regulatory and audit requirements around it), and then taking that a step further CRDTs, implemented correctly, provide me a nice interface for interacting with multiple version conflicts and resolving them in coherent ways without forcing me, or my other developers, to have to think up case-by-case resolution strategies and verify their correctness.
There really isn't a tremendous amount of complexity to using CRDTs. That's the point of them. They're easy to use. The complexity I'd really like to avoid if possible by avoiding CRDTs is the cognitive burden my team needs to have around distributed data and all it's horrible nuances to satisfy our use case. The knowing when and why to use them, not so much the how.
"At this kind of request rate I'd honestly just shove things in postgres and call it good." is very, very far away from a workable solution because my problem isn't request rate. The number of ops/sec could be hundreds or millions, and it doesn't really change my actual problem. No matter what the request rate is I could just write to a bunch of postgres instances that have a chash ring overlaid onto them... except now I have to deal with my actual problem still, which is redundancy, and local consistency in any postgres replica doesn't guarantee me much, I can't introduce a strong coordinator like a consensus protocol over the top of them, because it dumps my availability, and so I have to figure out how to safely deal with merge conflicts between the replicas... now I'm stuck figuring out how to build CRDTs on top of postgres anyway. So... what exactly did I win?
For another it would be really weird for Spanner to expose something CRDT shaped since Spanner is a strongly-consistent distributed database which depends heavily on global order and read/write locks driven by meticulously coordinated multi-site global wall-clock time and consensus groups.
In some ways it's almost the opposite of what I want... with exception of the fact that it's also distributed. I want extreme availability with lazy, weak coordination.
No, it's slightly more lazy in that that. It does timestamp coordination, but retrospectively.
1) An efficient, high-performance distributed persistence store for arbitrarily large CRDT's.
2) A Kafka-like highly-available distributed binary log w/ cheap topics, that doesn't require external coordination, and doesn't lose acknowledged writes (which I'll happily give up any shape of linearization guarantee for).