yosinski
A sort of related idea was explored with this site, where millions (ok, thousands) of users evolve shapes that look like whatever they want, but likely with a strong bias toward shapes recognizable to humans. Over time, many common motifs arise:
Good point. You could also do this with the gradient version too (fool in-house using gradients -> hopefully fool someone else's network), but the transferability of fooling examples might differ depending on how they are found.
Yep, true, might just take a while. On the other hand, even a very noisy estimate of the gradient might suffice, which could be faster to obtain. Perhaps someone will do that experiment soon. Maybe you could convince one of those students of yours to do this for extra credit?? ;).
> Likewise, I was not very surprised that you can produce fooling images, but it is surprising and concerning that they generalize across models.
Ditto x2.
> It seems that there are entire, huge fooling subspaces of the input space, not just fooling images as points. And that these subspaces overlap a lot from one net to another, likely since they share similar training data (?) unclear.
Yeah. I wonder if the subspaces found using non-gradient based exploration end up being either larger or overlapping more between networks than those found (more easily) with the gradient. Would be another interesting followup experiment.
Of course, if you're as clever as Tinbergen, you might be able to come up with patterns that fool organisms even without (1) or (2):
Agreed; the weaknesses reported should definitely not be taken to affect only convnets or only deep learning. Ian's "Explaining and Harnessing Adversarial Examples" paper (linked by @Houshalter) should be required reading :).
> backpropagation allows us to efficiently compute (with dynamic programming, basically) exactly the single most damaging noise pattern out of all billions.
True. By using backprop, one can easily compute exact patterns of pixelwise noise to add to an image to produce arbitrary desired output changes. However, it's an important detail that that most of the images in the paper (all except the last section) were produced without knowledge of the weights of the network or by using backpropagation at all. This means a would-be-adversary need not have access to the complete model, only a method of running many examples through the network and checking the outputs.
> ...there are billion tiny noise patterns you could add to the input.
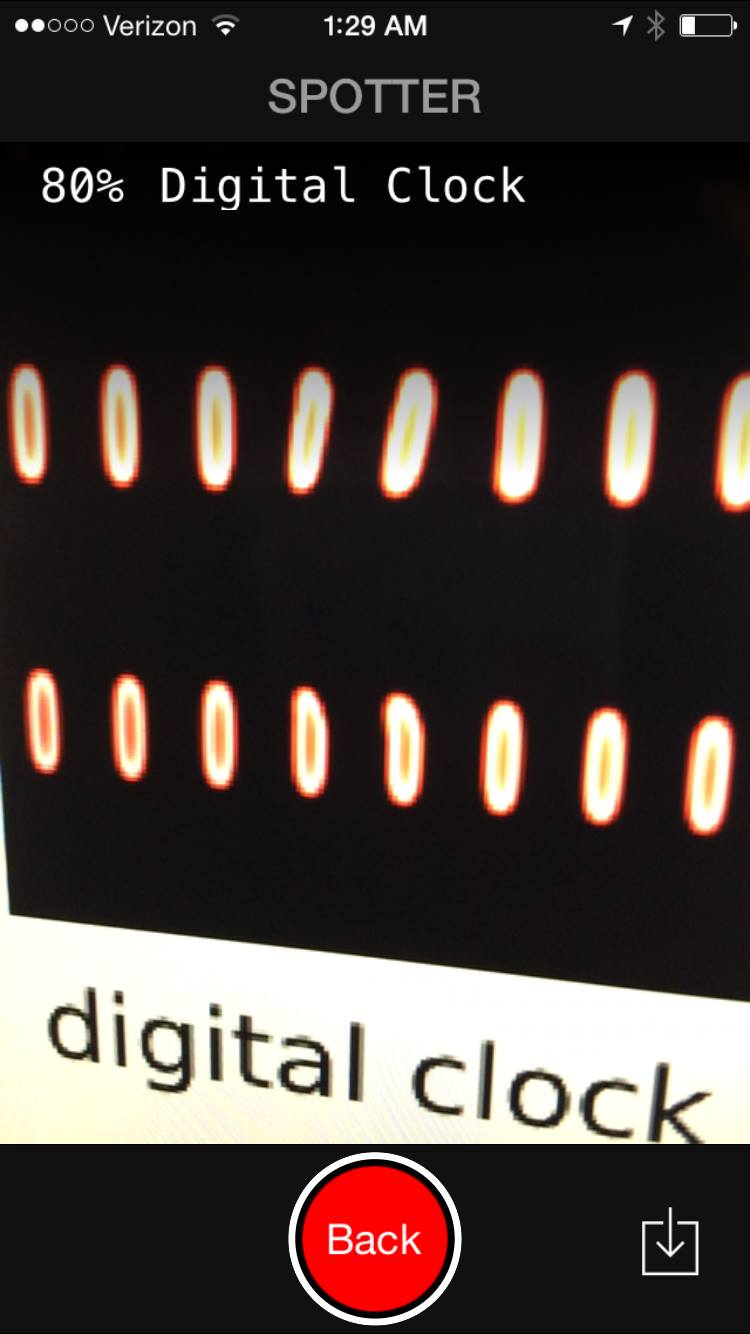
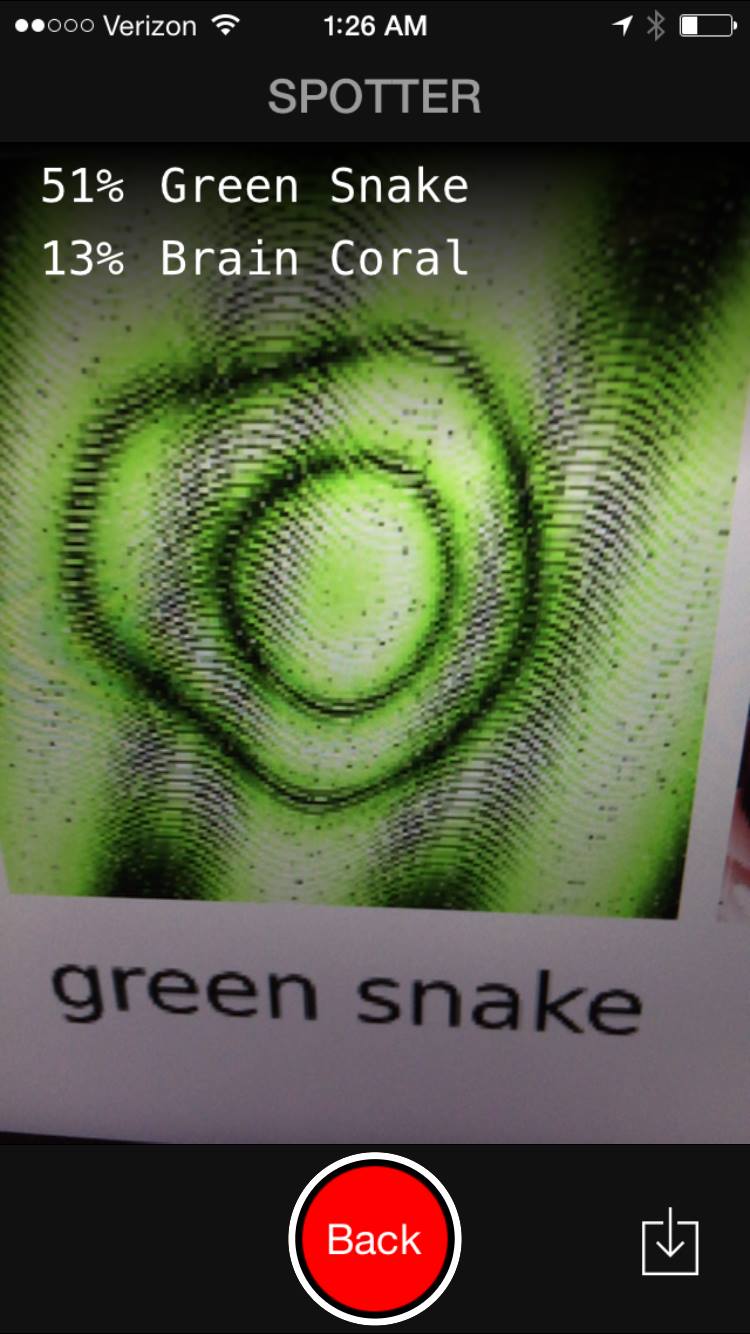
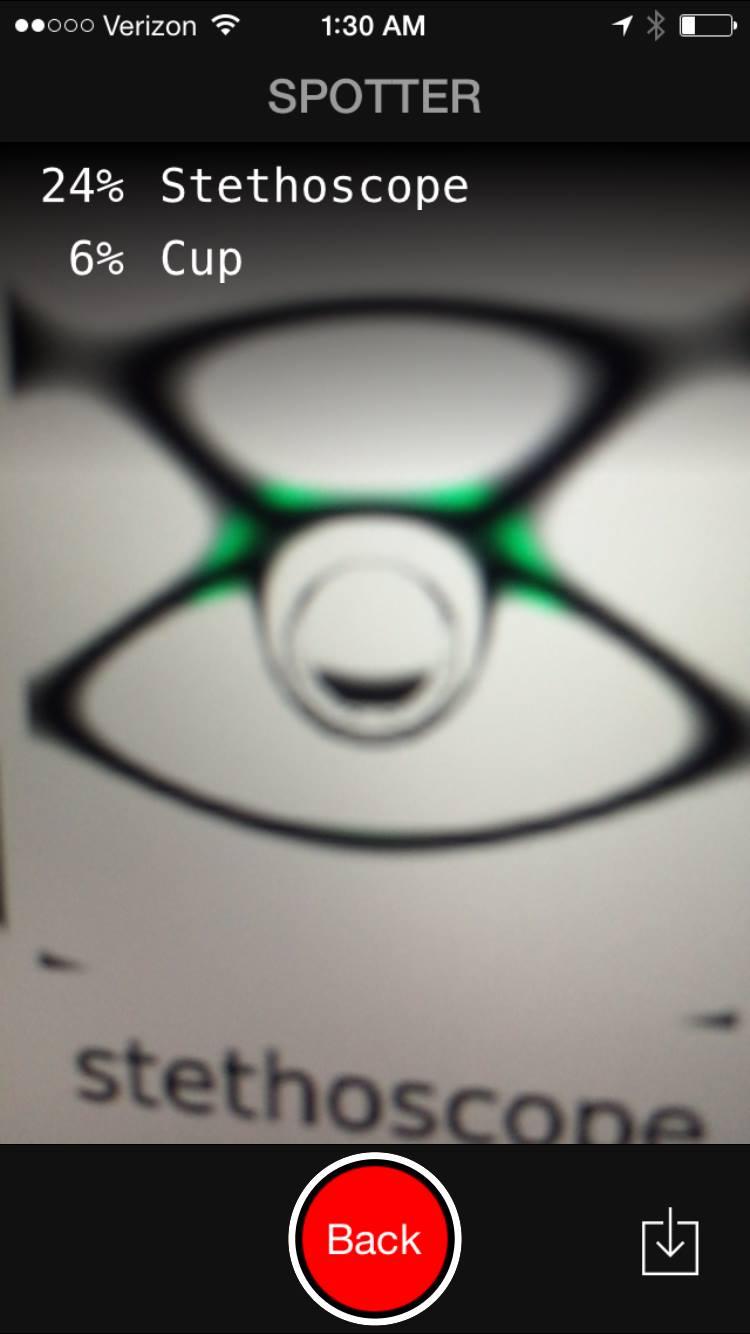
Perhaps because the CPPN fooling images were created in a different way (without using backprop), they seem to fool networks in a more robust way than one might think. Far from being a brittle addition of a very precise, pixelwise noise pattern, many fooling images are robust enough that their classification holds up even under rather severe distortions, such as using a cell phone camera to take a photo of the pdf displayed on a monitor and then running it through an AlexNet trained with a different random seed (photo cred: Dileep George):
http://s.yosinski.com/jetpac_digitalclock.jpg http://s.yosinski.com/jetpac_greensnake.jpg http://s.yosinski.com/jetpac_stethoscope.jpg
I thought this was surprising the first time I saw it.