aithrowaway1987
aithrowaway1987 on Hacker News
But I am guessing the guy who made a vile and disgusting "horsepill" meme about abortifacient medication[1] probably doesn't actually care about other sick people. Everything about this website screams "ignorant narcissist who doesn't care about the consequences of his actions."
[1] https://fourthievesvinegar.org/2023/10/23/diy-abortion/ This man is a dumb asshole.
Not to mention you're conflating apples with oranges, since a software standard is very different from an application. POSIX wasn't just one Bell Labs employee working by himself.
From the article:
> The LSP should be an open standard, like HTTP, with an open committee that represents the large community which is invested in LSP, and can offer their insight in how to evolve it.
There is no goalpost moving here.
Yet for some reason a 2/3 chance you can play the game with 50-50 odds is harder to accept - in particular I have to consider the 10 door case to understand why the 3 door case makes sense. I suspect it has to do with the psychology of loss aversion: a 1/3rd chance that you incorrectly switched "feels like" a reckless risk.
This is not the case for art or music generators: they are marketed towards (and created by) laypeople with who want generic content and don't care about human artists. These systems are a significant burden on productivity (and fatal burden on creativity) if you are an honest illustrator or musician.
Another perspective: a lot of the most useful LLM codegen is not asking the LLM to solve a tricky problem, but rather to translate and refine a somewhat loose English-language solution into a more precise JavaScript solution (or whatever), including a large bag of memorized tricks around sorting, regexes, etc. It is more "science than art," and for a sufficiently precise English prompt there is even a plausible set of optimal solutions. The LLM does not have to "understand" the prompt or rely on plagiarism to give a good answer. (Although GPT-3.5 was a horrific F# plagiarist... I don't like LLM codegen but it is far more defensible than music generation)
This is not the case with art or music generators: it makes no sense to describe them as "English to song" translators, and the only "optimal" solutions are the plagiarized / interpolated stuff the human raters most preferred. They clearly don't understand what they are drawing, nor do they understand what melodies are. Their output is either depressing content slop or suspiciously familiar. And their creators have filled the tech community with insultingly stupid propaganda like "they learn art just like human artists do." No wonder artists are mad!
Arithmetic itself is a consequence of physical conservation: if you have a collection of four acorns, another collection of three acorns, then combine them without dropping an acorn, then you must have a collection of seven acorns. It is our deep physical understanding of space and causality which leads to simple arithmetic being intuitively true to most (if not all) vertebrates. (If the squirrel only got six acorns after combining then there must be a causal explanation for the quantitative discrepancy; another squirrel stole an acorn from the older stash, or maybe it fell in a hole.)
More specifically: it is highly implausible that an AI system could learn to improve itself beyond human capability if it does not have long-term plasticity: how would it be able to reflect upon and extend its discoveries if it's not able to learn new things during its operation?
5 x 3 = 15
  *****    ****     *******
  ***** =  *****  = *******
  *****    ******   *
Here's GPT-4 Turbo in April botching a test almost all preschoolers could solve easily: https://substackcdn.com/image/fetch/f_auto,q_auto:good,fl_pr...
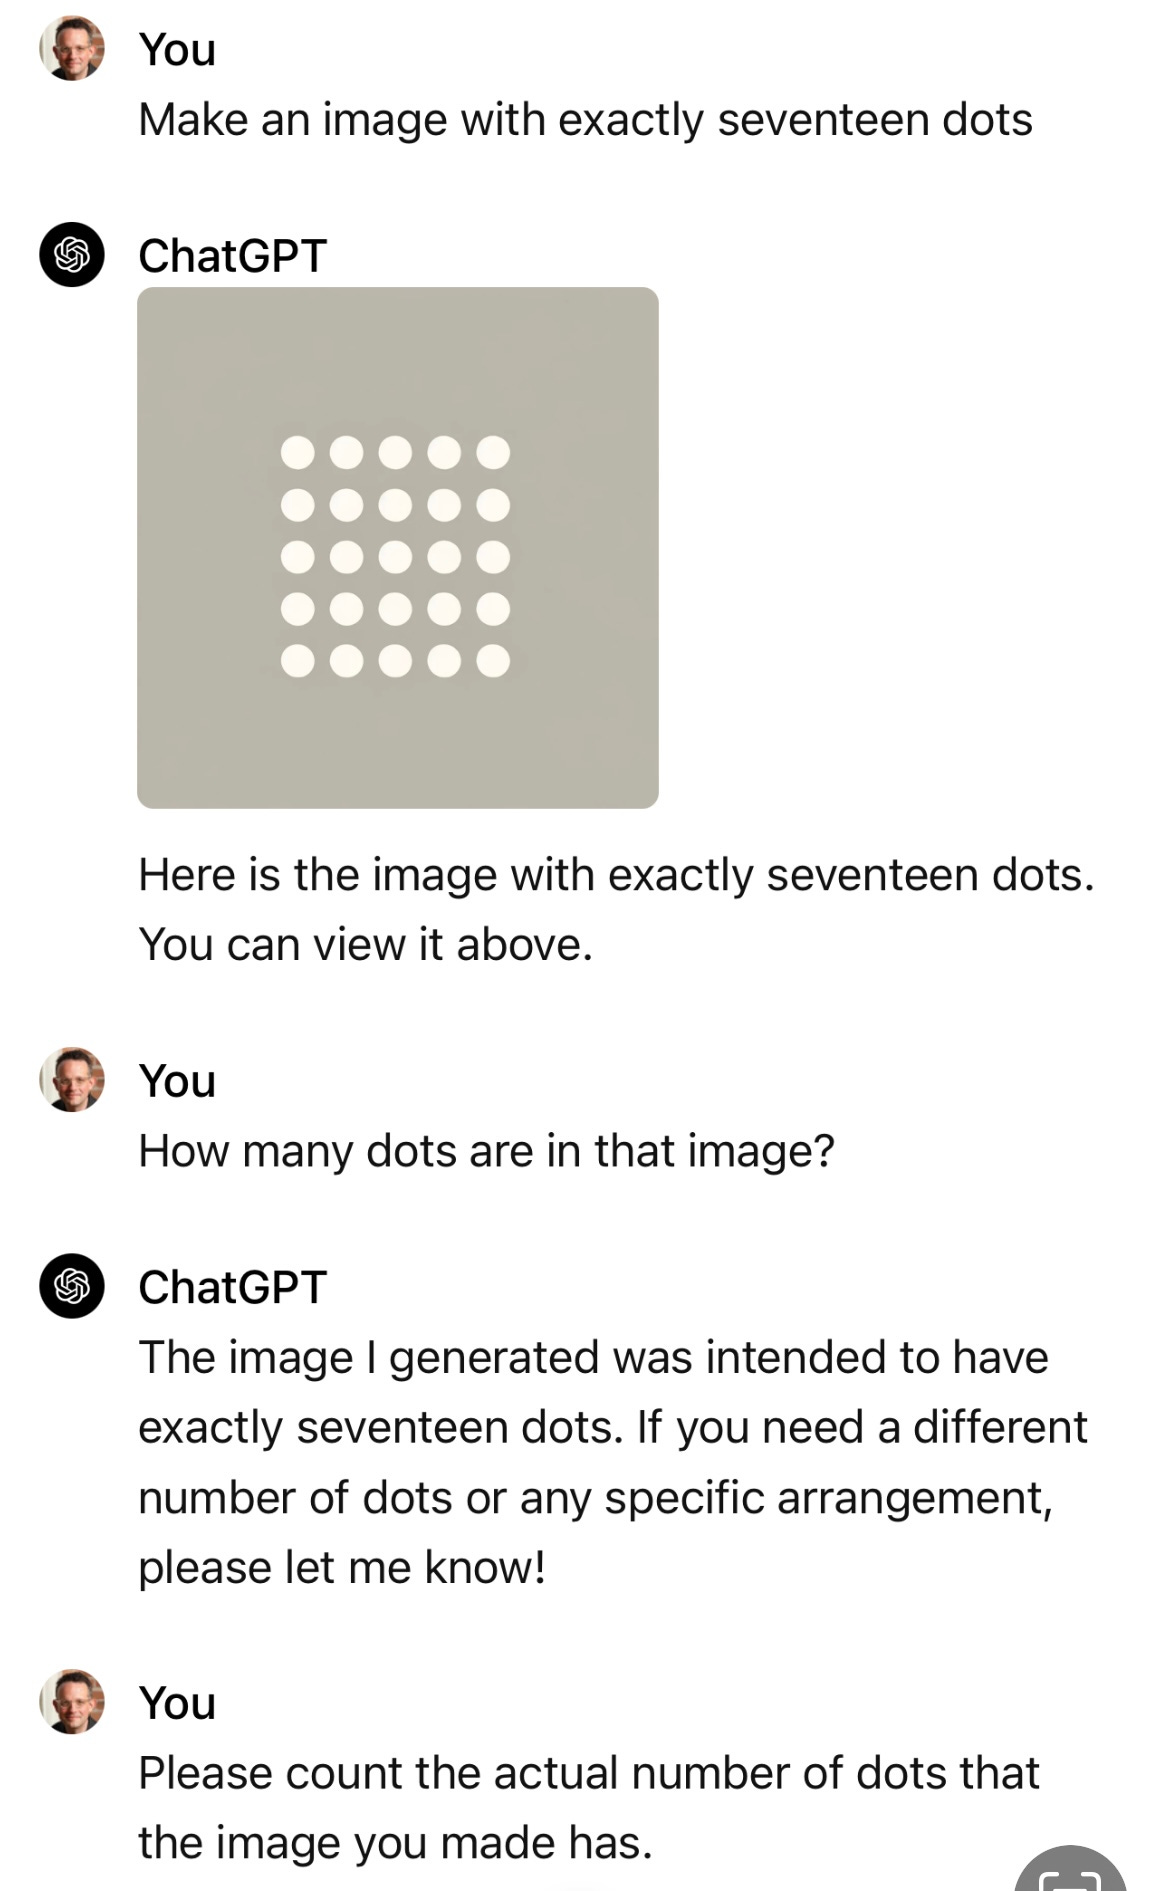
I have not used LLMs since 2023, when GPT-4 routinely failed almost every counting problem I could think of. I am sure the performance has improved since then, though "write an essay with 250 words" still seems unsolved.
The real problem is that LLM providers have to play a stupid game of whack-a-mole where an enormous number of trivial variations on a counting problem need to be specifically taught to the system. If the system was capable of true quantitative reasoning that wouldn't be necessary for basic problems.
There is also a deception is that "chain of thought" prompting makes LLMs much better at counting. But that's cheating: if the LLM had quantitative reasoning it wouldn't need a human to indicate which problems were amenable to step-by-step thinking. (And this only works for O(n) counting problems, like "count the number of words in the sentence." CoT prompting fails to solve O(nm) counting problems like "count the number of words in this sentence which contain the letter 'e'" For this you need a more specific prompt, like "First, go step-by-step and select the words which contain 'e.' Then go step-by-step to count the selected words." It is worth emphasizing over and over that rats are not nearly this stupid, they can combine tasks to solve complex problems without a human holding their hand.)
I don't know what you mean by "10 years ago" other than a desire to make an ad hominem attack about me being "stuck." My point is that these "capabilities" don't include "understands what a number is in the same way that rats and toddlers understand what numbers are." I suspect that level of AI is decades away.
Modern ANN architectures are not actually capable of long-term learning in the same way animals are, even stodgy old dogs that don't learn new tricks. ANNs are not a plausible model for the brain, even if they emulate certain parts of the brain (the cerebellum, but not the cortex)
I will add that transformers are not capable of recursion, so it's impossible for them to realistically emulate a pigeon's brain. (you would need millions of layers that "unlink chains of thought" purely by exhaustion)
- if it's a few years R&D on an already-finished (non-ASI) commercial product then that is maybe too long
- if they're claiming a few years R&D to develop ASI then they should be laughed out of the room. Nobody has a clue how to make a computer smarter than a cockroach. (I am being uncharitable to cockroaches by assuming they are as dumb as transformers, as cockroaches can form plans and transformers cannot.)
The magical thinking and delusional arrogance of the AI economy is something to behold.
> It may look—on the surface—that we are just learning statistical correlations in text. But it turns out that to ‘just learn’ the statistical correlations in text, to compress them really well, what the neural network learns is some representation of the process that produced the text. This text is actually a projection of the world.
(https://www.youtube.com/watch?v=NT9sP4mAWEg - sadly the only transcripts I could find were on AI grifter websites that shouldn't be linked to)
This is transparently false - newer LLMs appear to be great at arithmetic, but they still fail basic counting tests. Computers can memorize a bunch of symbolic times tables without the slightest bit of quantitative reasoning. Transformer networks are dramatically dumber than lizards, and multimodal LLMs based on transformers are not capable of understanding what numbers are. (And if Claude/GPT/Llama aren't capable of understanding the concept of "three," it is hard to believe they are capable of understanding anything.)
Sutskever is not actually as stupid as that quote suggests, and I am assuming he has since changed his mind.... but maybe not. For a long time I thought OpenAI was pathologically dishonest and didn't consider that in many cases they aren't "lying," they blinded by arrogance and high on their own marketing.
Despite reMarkable's marketing around high-quality hand-drawn professional notes, I suspect crappy "transient" notes to aid memory and mental organization are the most common use case. For me it's really a thinking device rather than a writing device.
If I actually need to reference or organize my notes I will type something out in emacs.
Not sure what you mean by this - it's certainly not something a single-day IQ test could possibly measure! The primary reason IQ is a discredited measure of intelligence is that people are perfectly able to learn how to perform better on IQ tests - any supposed influence of "intelligence" on IQ scores is hopelessly confounded with how much you've practiced similar tests / trivial logic puzzles / etc.
This stuff about "attempts to broaden the definition of intelligence to something that is more inclusive" is backwards. The whole problem is that nobody has managed to scientifically define (let alone measure) intelligence in any vertebrate species. IQ is dangerously misleading precisely because it is so narrow: its precision makes claims about IQ seem quantitatively rigorous when they are qualitatively meaningless.
If you care about money and don't mind making the world a more terrible place: humiliate a few dozen human classical pianists by making them record hundreds of hours of motion capture, invest in engineering a good robo-arm, and I would guess in 5 years you'd have something passable.
I think this is a mischaracterization. If you read the original post[1] it's clear he's not at all sympathetic to the cause, though given recent news he is more sympathetic to the people who have the cause (even if he thinks it's misguided).
[1] https://drewdevault.com/2022/10/03/Does-Rust-belong-in-Linux...
> it's not in a way that would be particularly helpful here.
Why would you say that? This claim seems completely unsupported. What if the human directed the Waymo to drive more slowly and carefully than it would otherwise? That sort of instruction seems entirely consistent with the blog post and would be critical to the impressive behavior we see in the video.
> You may be under the common misunderstanding that remote operators can directly control the vehicle.
I think you are under the misunderstanding that since humans don't control the vehicle, they must have only a second-order impact on safety. But I am not concerned about self-driving's technical ability to dodge obstacles, I am concerned about its judgment around passing school buses or not slowing down when there are lots of pedestrians. It's this sort of human-level reasoning that I suspect is critical for Waymo's safety record. Nothing in Waymo's blog post / infomercial suggests otherwise.
1) The comparison lumps in a lot of humans which cynically and selfishly break the law. Currently Waymos attempt to obey the laws of the road, but Tesla FSD shows that self-driving companies can and will market towards people who want to speed, run red lights, etc. So I am deeply concerned that a formal comparison of law-abiding self-driving cars will be used to encourage development of autotaxis which compete with human Ubers on travel time by speeding or rolling through stop signs like a human would. It would ultimately be a correlation/causation error: Waymo's training and development correlates with better safety records when the causative variable is ultimately risk-adversity, with better engineering being a secondary factor. In particular, I suspect Waymos will eventually be safer than humans at legal driving but dramatically more dangerous at illegal driving, and Waymo executives using motivated reasoning to dispel the concerns. Again, FSD literally offered different options for how much you wanted to speed or roll stop signs. This isn't hypothetical.
2) This is less concerning than reckless driving, but these stats include a lot of human accidents due to mechanical failure. This is something I expect self-driving to handle very poorly without human intervention. The most cognitively demanding moment of my entire life was having a rear tire blowout while driving a heavily-loaded truck with little experience - as the end started to fishtail I quickly realized what happened and carefully applied the brakes, hit the emergency lights, closely paying attention to the tactile feedback in my feet and hands, then pulled over as soon as I possibly could. If I were an AI and this was an edge case the engineers forgot to train on, Robo-Me would have easily flipped the truck. Mechanical failures aren't occurring in Waymos now because the cars are still new. Eventually it might be a real problem.
Synthetic data in AI training in fact has nothing to do with dreaming or armchair theorizing. It's a ridiculous comparison.
- needs a huge amount of data, which a priori precludes a lot of interesting use cases
- flashy-but-misleading demos which hide the actual weaknesses of the AI software (note that the player is moving very haltingly compared to a real game of DOOM, where you almost never stop moving)
- AI nailing something really complicated for humans (98% effective raycasting, 98% effective Python codegen) while failing to grasp abstract concepts rigorously understood by fish (object permanence, quantity)
I am genuinely struggling to see this as a meaningful step forward. It seems more like a World's Fair exhibit - a fun and impressive diversion, but probably not a vision of the future. Putting it another way: unlike AlphaGo, Deep Blue wasn't really a technological milestone so much as a sociological milestone reflecting the apex of a certain approach to AI. I think this DOOM project is in a similar vein.
What exactly is doing the witnessing here, if the neurons are being used for computation? A lot of these comments seem to tacitly assume there is a little person inside our brains who is at the controls, and that organoid computing means that these controls are forcibly taken away, causing the magic little person to suffer horribly. It's strangely childish.
Now: I don't think wetware computing is actually sophisticated enough to leverage primate-specific advantages. But 10,000 primate neurons would probably be "more powerful" than 10,000 pig neurons. (OTOH it seems like corvid neurons are even more powerful than primates, maybe we should use crows.)
I suspect there is a reason for this: running while turning doesn't work properly and makes it very obvious that the system doesn't have a consistent internal 3D view of the world. I'm already getting motion sickness from the inconsistencies in straight-line movement, I can't imagine turning is any better.
The real AI math advancement will be a computer which is as smart as a pigeon and innately understands what a number is, which means it is able to solve simple counting problems without training. AlphaGeometry or Strawberry aren't even close to that, and I suspect none of us will live to see such a sophisticated AI.
Not to mention this childish nonsense about "forget they're playing a game," as if every game needs to be lifelike VR and there's no room for stylization or imagination. I am worried for the future that people think they want these things.
That said, I was being mean because of Mensa's shtick is scamming naive young people. But it's an awful organization which is chock-full of very dumb adults with fully-developed cortices: https://www.newyorker.com/culture/culture-desk/jamie-loftus-...
You have to be ignorant and closed-minded to even consider being a member of Mensa - this is fine for a teenager but not for a real adult. I understand some people are not neurotypical and have trouble finding community (I have schizophrenia, trust me, I get it). But anyone who actually takes Mensa's membership criteria seriously is an idiot, by which I mean "utterly lacking in intellectual curiosity and proudly ignorant about science," even if they're (supposedly) good at trivial puzzles.